Why Agentic AI Workloads Break Traditional Software Testing
Agentic AI breaks three core enterprise testing assumptions: fast execution, cheap retries, and reproducible outputs. Here is why pilots hide the cracks.
👁 114 reads
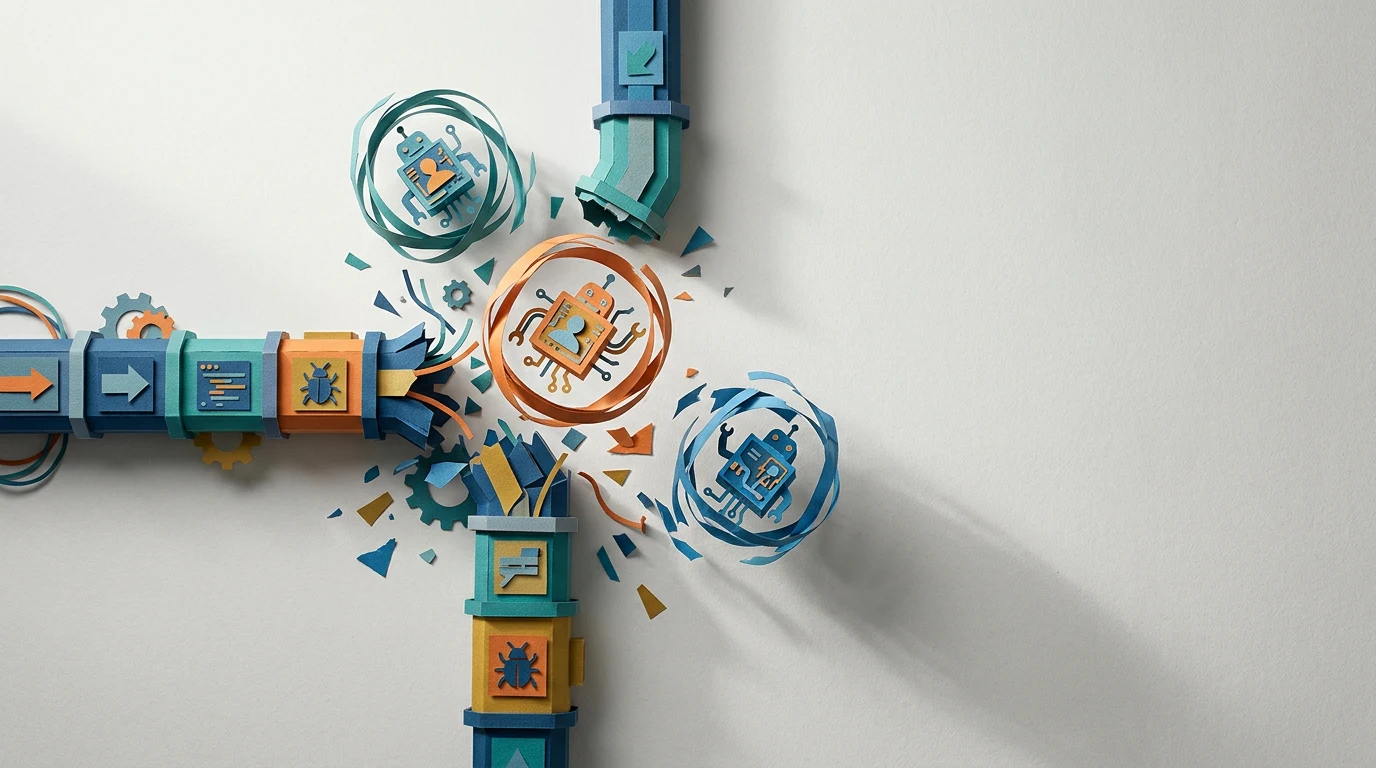
Traditional enterprise systems rely on three foundational assumptions: tasks finish quickly, retries are practically free, and identical inputs produce predictable outputs. Agentic workloads break all three simultaneously. That fundamental shift explains why AI agent pilots run smoothly under human supervision, only to fall apart once deployed into production.
In an analysis published in SiliconAngle, M. Touheed outlines three specific cracks that agentic architectures introduce into conventional software testing practices.
Three core assumptions AI agents break
First, execution duration. An agentic task can run for minutes rather than milliseconds - long enough to trigger timeout thresholds that no layer in the existing stack was ever built to handle. Systems that appeared completely stable start dropping requests in ways that seem baffling until you inspect the actual elapsed runtime.
Second, the cost of retries. In traditional software, retries carry virtually zero marginal cost, so engineering teams configure them liberally. With AI agents, every retry against a metered model consumes billable tokens and compute, regardless of whether the final output is usable. Because cloud API and model billing operates asynchronously on monthly invoicing cycles, cumulative retry expenses accumulate silently - only surfacing weeks later when the bill arrives.
Third, the inability to reproduce errors. According to Touheed, this is the most disruptive shift. Standard debugging practices rely on re-running the failed routine and watching where it breaks. With non-deterministic agents, that playbook fails: without a comprehensive, step-by-step trace of agent decisions, tool invocations, and API payloads, there is nothing reliable to inspect, reducing root-cause analysis to pure speculation.
Google · Your sourcesQuantslant higher in your Google - one clickAdd to preferred sources →Why pilot projects fail to catch these flaws
Evaluation environments mask these problems because during an interactive pilot, a human operator acts as the runtime error handler. They read every output, catch hallucinations, and manually correct errors as they occur. Costs remain visible because retries are triggered one by one. Under these conditions, the lack of an audit trail or automated reproduction mechanism goes unnoticed.
Automated agent workflows work under very different conditions: they execute headless, with no human sitting at the console. A workflow that performed reliably when a user prompted the AI and reviewed each step behaves very differently when a cron job triggers it 400 times overnight without supervision. The underlying failure modes existed from day one; human operators simply absorbed and corrected them in real time.
The takeaway for engineering leaders is clear: before shifting agentic workloads into automated production, inventory every single manual intervention performed during evaluation, and explicitly identify which automated mechanism will handle that responsibility. Touheed also recommends rethinking budget metrics: instead of tracking the cost per API call, track the cost per completed unit of work - a number that factors in discarded attempts and reveals the true operational expense.
It is an analysis worth sharing with any team celebrating a successful pilot and preparing to push autonomous agents into production next quarter.
More on this from QUANTSLANT


 ai tools·Google SynthID Detector Is Live: What It Detects and MissesGoogle opened SynthID Detector to everyone. Here is how watermarking works, what the results actually mean, and how to verify AI-generated media.