AWS Strands Decider 2B Tested: Fast Open Source Decision Model
Strands Decider 2B from AWS picks answers instead of generating text. We tested its latency, accuracy, and VRAM usage on an RTX 4090.
👁 113 reads
Strands Decider 2B is an open decision model from AWS: instead of generating open-ended text, it selects an answer from a provided list and outputs a confidence score. It features 2 billion parameters, an Apache-2.0 license, and AWS published not just the weights, but the training datasets and scripts as well. We ran it locally on an RTX 4090: it consumed 3.8 GB of VRAM and routed non-English customer support tickets flawlessly in 135 ms. For broader context and a comparison with Cloudflare Clef, check our guide to AI decision models.
What Is Strands Decider 2B?
The model was released on October 1, 2026, by the Strands Labs team at AWS (authored by Marc Brooker, Mike Chambers, and Fabio Nonato de Paula). Its name originates from Strands Agents, the open-source AWS framework for building agents. Here are the core specifications:
- Base model: Qwen3.5-2B-Base. AWS removed the standard language head and replaced it with a pointer head containing just over 1 million parameters, which evaluates the hidden state at the position of each option.
- Fine-tuning: A LoRA rank 16 adapter. The checkpoint
StrandsAgents/strands-decider-2B-hobson-v19is hosted on Hugging Face; the adapter weighs 67 MB, and the base model downloads automatically on the first launch (4.3 GB in our test). - License: Apache-2.0 for the model weights, code, and training recipe; the underlying Qwen3.5-2B-Base model also uses Apache-2.0.
- Transparency: The
strands-labs/strands-deciderrepository includes full training scripts, a list of 29 public datasets (including BANKING77, CLINC, AG News, HotpotQA), and raw evaluation data. - Installation: Running
pip install strands-deciderprovides both a command-line tool and an HTTP server. - API: Fully compliant with the System One specification, the same standard used by Jev from TypeSafe, Cloudflare Clef, and Kev.
How You Query the Model
Like any decision model, Strands Decider accepts context state and named queries across three primary types:
| Type | Example | Output |
|---|---|---|
choice |
Which department: payments, shipping, returns? | Selected option + confidence + probability distribution |
noul |
Is the customer upset? | Probability of “yes” |
score |
Urgency level: can wait / this week / today? | Expected value score + distribution |
There is no fixed limit on the number of options because class labels are passed dynamically at runtime rather than being hardcoded into the architecture. Output is produced in a single forward pass without an autoregressive generation loop. The context state is evaluated once, and individual questions are processed against a cached representation, meaning extra questions add virtually no latency.
AWS Benchmark Numbers
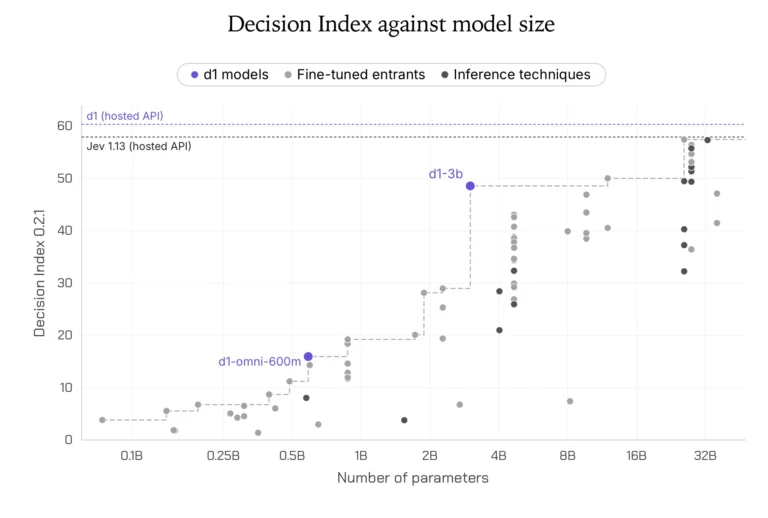
- JevBench (231 public tasks): 167 correct decisions (72.3%). AWS notes this ranks 3rd among 33 models in the 2B class, and 1st out of 30 when excluding models slightly larger than 2B.
- JevBench Easy subset: 100% accuracy.
- Latency: Median around 115 ms on an RTX 3090, and roughly 153 ms on an M3 MacBook.
- Internal evaluations: Ranging from 64.1% (short-context tasks across 6,000 samples) up to 89.8% (unanswerable question detection on MuSiQue).
AWS is upfront about the trade-offs. The model trails behind large reasoning models on complex multi-step problems and is entirely unsuitable for code generation, free-form chat, or summarization. The model card also notes that it attends less strongly to the query text than to the input document: changing the phrasing of a question while keeping the state and options identical often yields the same output, so you need unambiguous option labels.
Our Hands-On Test: Support Ticket Routing
We tested the model on 30 customer service tickets typical for an e-commerce shop or SaaS app, spanning 5 tickets across 6 departments (payments, shipping, returns, account, outages, sales), including typos and missing diacritics. Because multilingual routing is a common challenge, we tested it in Polish alongside English. Each ticket was evaluated on two criteria: department classification and whether immediate same-day handling was required. Hardware setup: RTX 4090, Windows 11, PyTorch 2.11.
| Variant | Department Accuracy | Urgency (0.5 Threshold) | Median Latency |
|---|---|---|---|
| Polish tickets, Polish department labels | 30/30 | 24/30 | 135 ms |
| Polish tickets, English labels | 30/30 | 26/30 | 135 ms |
| Full English benchmark | 29/30 | 26/30 | 130 ms |
- VRAM footprint: Peaked at 3.8 GB VRAM, with initial model loading taking 16 seconds.
- Department routing: 100% accurate in Polish. Its only misstep in English involved a plan change mid-billing cycle, which the model categorized as payments instead of sales-a confusing case that tripped up most other models we evaluated.
- Urgency scoring: We ran into a calibration issue. The “yes” probability for 6 genuinely urgent tickets fell between 0.22 and 0.47. None cleared the default 0.5 threshold, meaning the default setting flagged zero tickets as urgent. However, the relative ranking was solid: lowering the threshold to 0.4 brought the urgency score to 26/30.
- Routing confidence: Median of 0.86, with a low of 0.31. By comparison, the larger Clef-flash scored a median confidence of 0.97.
On the exact same GPU, Gemma 4 12B running via Ollama with structured JSON outputs also achieved 30/30 accuracy, but required 413 ms. Llama 3.1 8B managed 173 ms with an accuracy of 25/30. See our comprehensive comparison of eight models in the AI decision models guide.
Strands Decider vs. Cloudflare Clef
| Feature | Strands Decider 2B | Clef-flash |
|---|---|---|
| Parameters / Download | 2B, ~4.4 GB download | 9B, 19 GB |
| VRAM during our test | 3.8 GB | 18.3 GB |
| Median latency (RTX 4090) | 135 ms | 112 ms |
| Image & video support | No | Yes |
| Hosted API | Self-hosted only | Workers AI, $0.09 / million tokens |
| Training data | Public datasets published | Internal synthetic datasets |
| CPU / Mac compatibility | Yes | Practically requires a 24 GB GPU |
We recommend Strands Decider when you need to run inference on a laptop, a small instance without an expensive accelerator, or directly on CPU, and when having a transparent, reproducible fine-tuning pipeline matters. Choose Clef-flash if you have 24 GB VRAM available, need multimodal input processing, or prefer a managed endpoint. Read more about Clef in our dedicated Cloudflare Clef breakdown.
Quickstart: Run It in 3 Steps
- Install PyTorch (with CUDA support if running an NVIDIA GPU), then install the package via
pip install strands-decider. It requirestransformersversion 5.15 or newer. - Run a CLI classification:
strands-decider ask StrandsAgents/strands-decider-2B-hobson-v19
  --state "Kurier zostawił karton pod drzwiami sąsiada i teraz go nie ma"
  --choice "Który dział?=platnosci,dostawa,zwrot,konto"
  --noul "Czy klient jest zdenerwowany?"
Translation: State: “Kurier zostawił karton pod drzwiami sąsiada i teraz go nie ma” (“The courier left the box at the neighbor’s door and now it’s gone”). Choice: “Który dział?” (“Which department? = payments, delivery, return, account”). Noul: “Czy klient jest zdenerwowany?” (“Is the customer upset?”).
- Spin up the local API server:
strands-decider serve StrandsAgents/strands-decider-2B-hobson-v19 --port 8000and post your requests to/v1/systemone.
On Windows systems, Hugging Face Transformers may warn about missing flash-linear-attention and causal-conv1d packages. The model runs fine without them (our 135 ms benchmark was recorded without these optimizations installed), just slightly slower than its peak potential. Keep in mind the built-in server binds exclusively to 127.0.0.1 with no authentication by default, so you will need a reverse proxy or auth layer before deploying it to production.
Sources
- Strands Agents: Introducing Strands Decider 2B (October 1, 2026)
- Strands Decider 2B on Hugging Face
- Source Code on GitHub
- Our local tests: October 5, 2026, RTX 4090.
Frequently Asked Questions
How much GPU VRAM does Strands Decider 2B use, and how fast is it?
The model requires roughly 3.8 GB of VRAM. In our benchmark on an RTX 4090, the median inference latency was 135 ms. According to official AWS metrics, median latency sits around 115 ms on an RTX 3090 and approximately 153 ms on an Apple M3 MacBook.
What license is Strands Decider 2B released under, and what did AWS share?
Strands Decider 2B is distributed under the Apache-2.0 license, covering the model weights, codebase, and training recipes. AWS published the full training scripts, a list of 29 public training datasets, and raw benchmark evaluations in the strands-labs/strands-decider GitHub repository.
How accurate is Strands Decider 2B for ticket classification?
In our test evaluating customer support tickets across 6 distinct departments, the model scored a perfect 30 out of 30 for department routing. For urgency detection, the default 0.5 threshold was under-calibrated and marked none as urgent; recalibrating the decision threshold down to 0.4 restored accuracy to 26 out of 30.
More on this from QUANTSLANT



 news·Liquid AI d1: Open Decision Model, AA Benchmark, and PerformanceLiquid AI released d1: a decision model starting at $0.04/M input tokens with open d1-3B weights. We review benchmarks, pricing, and our classification tests.