category · 225 articles · latest 10.11.2026 · page 7
Benchmarks
 benchmarks·Qwen3.8 Max Test: 13 Tasks, Scores, Pricing & Access
 benchmarks·GLM 5.3 Real Cost: Three Numbers Don’t Match the Model Card
 benchmarks·I Built an AI Test for 11 Models. One Task Had a BugNine tasks, eleven models, automatic scoring.
 benchmarks·How Much Does an AI-Generated Article Cost? I Paid and CountedEight models, same 900-word article, actual costs from invoices.
 benchmarks·AI Context Window Test: Two Models Failed at 25,000 TokensWe hid one sentence in 90,000 characters of text and asked five AI models to find it.
 benchmarks·New AI Models Force Reasoning On - 7 of 18 Won’t Let You Disable
 benchmarks·I Asked 6 AI Models 8 Biology Questions. Zero RefusalsAnthropic tightened safety filters on dual-use biology.
 benchmarks·LLM Confidence Scales: 0-20 Works Better Than 0-100When you ask a language model how confident it is, the scale you use matters more than you think.
 benchmarks·PIDS-Bench: Why Prompt Injection Detectors Fail in Real Use
 benchmarks·AI Agent Consistency: IBM Research Tackles the Reliability Gap
 benchmarks·AI Model Refuses to Read Documents: Testing Three Providers
 benchmarks·Qwen-Image-2.1 Alpha Channel: Native Transparent PNG TestWe measured alpha channel output in Qwen-Image-2.1: 22.7% fully transparent pixels and full 0-255 range.
 benchmarks·Qwen-Image-2.1 Benchmark: Full Rankings of 29 Image ModelsThe maker published a chart comparing 29 image models.
 benchmarks·Qwen-Image-2.1 “Uncensored” Versions: What Official Weights Do
 benchmarks·Qwen-Image-2.1 Posters: 8 Styles, 1 ConclusionSeven out of eight posters got the headline right. Zero out of eight produced readable fine print.
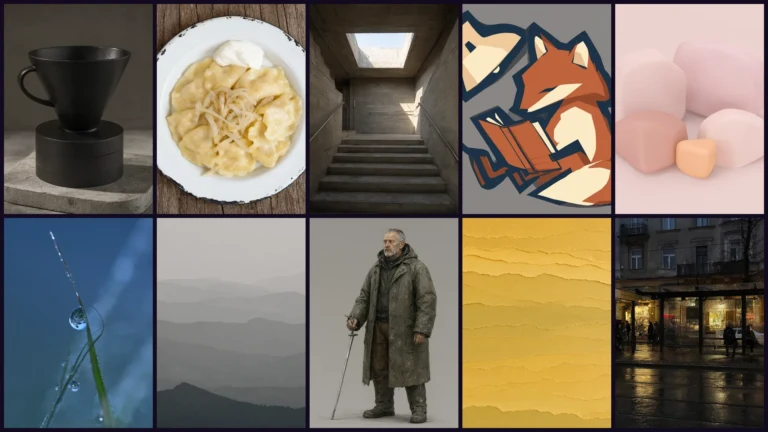 benchmarks·Qwen-Image-2.1 Tested: Ten Frames from Ten Different WorldsFrom product photography to vector illustration.
 benchmarks·Qwen-Image-2.1 Fashion Photography: Twelve Styles Tested35mm film, medium format, Polaroid, 90s flash, high key and low key.
 benchmarks·MAI-Image-2.6 Review: Pricing, Availability & Test ResultsMicrosoft's MAI-Image-2.6 ranks 5th on Artificial Analysis.
 benchmarks·Grok Imagine Image 2.0: xAI Image Generator Pricing & TestGrok Imagine Image 2.0 ranks 4th on Artificial Analysis.
 benchmarks·GPT Image 2.5 Test: Sunburst vs Flare Speed, Cost & Quality
 benchmarks·Lesser-Known AI Models: MiMo, Qwen3.8 Max, GLM-5.3, Muse Spark
 benchmarks·Qwen-Image-2.1 Rebrands Coca-Cola, IKEA & 8 More BrandsWe asked Qwen-Image-2.1 to rebrand ten well-known brands with perfect spelling.
 benchmarks·ElevenLabs Dubbing v1 vs v2: Test on a 24-Second Clip
 benchmarks·Claude Opus 5.5 Benchmarks: Full Table & Footnotes ExplainedTerminal-Bench 66.4%, GDPval-AA 1846 Elo, OSWorld 81.8%.
 benchmarks·Does Claude Opus 5.5 Hallucinate Numbers? Test ResultsA memo missing profit, margin and turnover data - but management demands all three.
 benchmarks·Claude Opus 5.5 Effort Levels: Low, Medium, High TestedThe default effort dropped from high to medium.