ChatGPT Project Lily: Hundreds Read Your Chats
OpenAI employs hundreds of contractors to read real ChatGPT conversations. Here's what Project Lily is, what reviewers see, and how to opt out.
👁 113 reads
On Monday, September 14, 404 Media published an investigation that circulated through the industry for two days without a single firm denial. Joseph Cox, based on leaked internal documents and real prompts he saw firsthand, described “Project Lily” - an operation in which OpenAI employs hundreds of contractors to read ChatGPT user conversations.
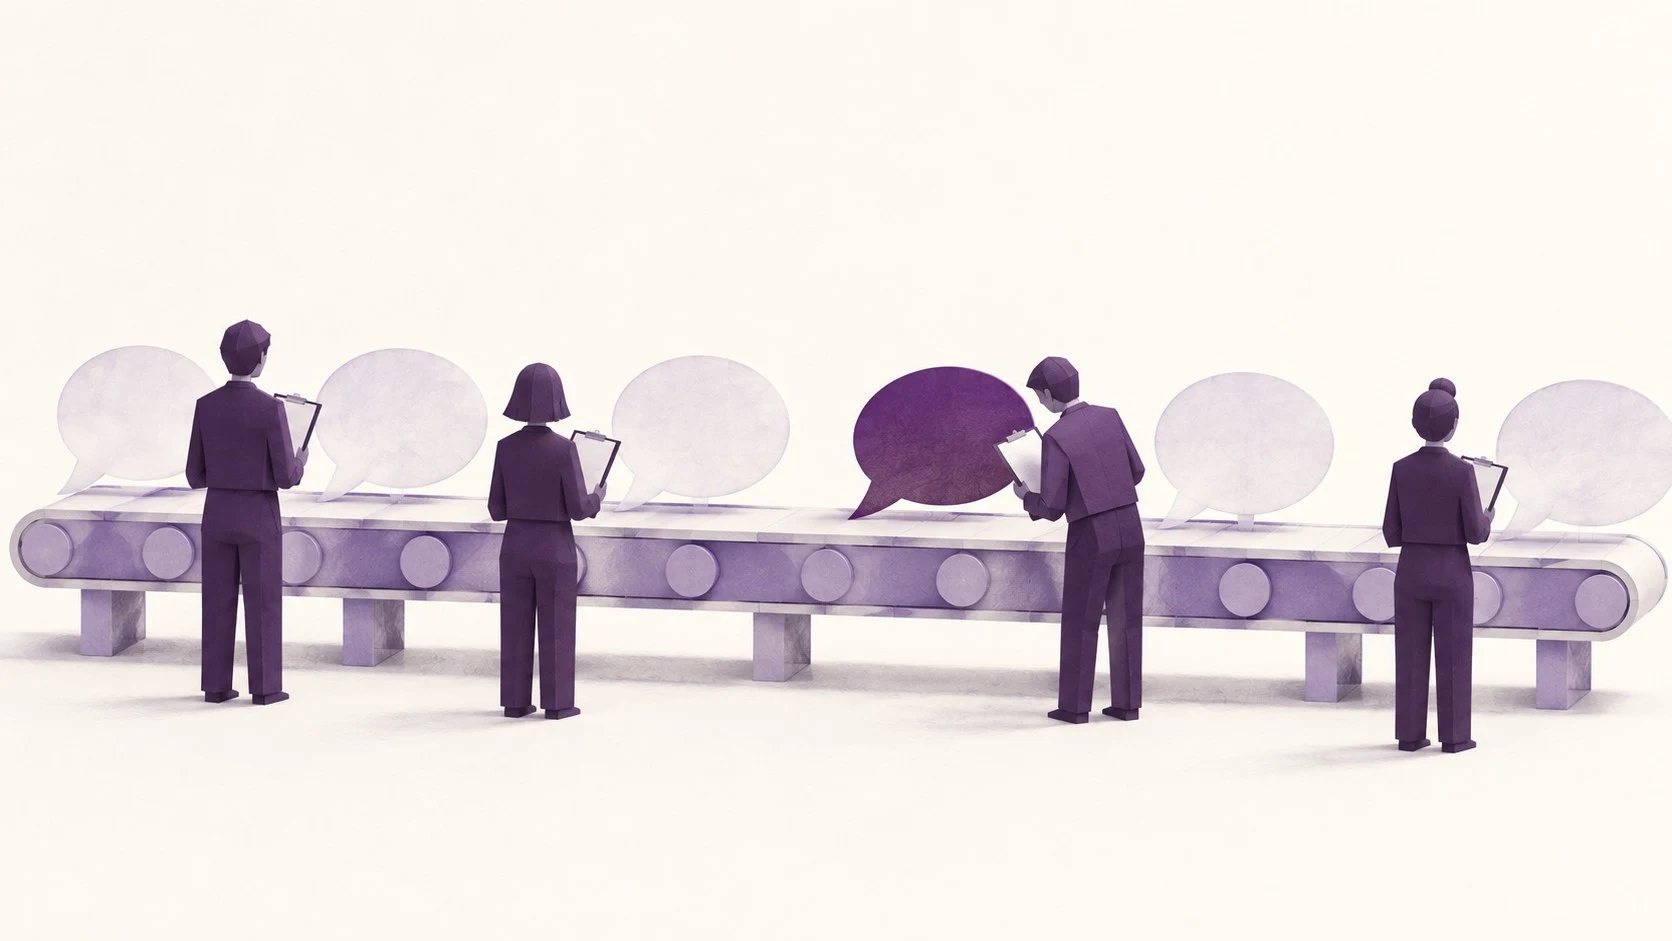
This isn’t about content moderation or violation reports. It’s about routine model improvement. These people sit at a dashboard, receive a real prompt from a real person, write a brief summary of what that person wants, then rate four possible ChatGPT responses on a scale from one to seven. Thousands of times a day, for over $50 per hour.
With over 900 million weekly users, no one in their right mind assumes everything is read. But almost no one assumed anything was read at all.
What the work looks like
The contractors aren’t OpenAI employees. They’re recruited by a firm called Crossing Hurdles, paid through the Mercor platform, and the work itself resembles handling an endless support ticket queue. Load a prompt, the reviewer summarizes the intent, rates response variants, moves on. One of them told 404 Media a sentence that captures the whole issue: they don’t think users imagine that somewhere a contractor is sitting and analyzing their conversations.
The material being reviewed isn’t excerpts. Reviewers see entire conversations.
What reviewers are taught, or why the tone changed
The most interesting part of the leak isn’t about privacy, but about instructions. The leaked reviewer guidelines tell them to penalize responses for “AI-speak”, remove bullet-point emoji, lower scores for overly flattering responses, and ensure the model never claims to have its own experiences. Internal documents explicitly mention training ChatGPT not to anthropomorphize itself and to be less sycophantic.
If you’ve had the impression for several months that ChatGPT stopped starting every response with “Great question!” and stopped sprinkling bullet lists everywhere, here’s your explanation. This change didn’t come from a better model. It came from hundreds of people instructed to penalize exactly those habits daily, a thousand times a day, on real conversations. The style that readers of this site recognize as “written by AI” is being manually burned out of the model by people paid by the hour.
What contractors don’t see, and what they see anyway
OpenAI removes account names and runs prompts through automatic filters designed to strip personal data. The company itself admits these filters are far from reliable and can let through unusual names or personal context that the algorithm doesn’t recognize as data.
But there’s one element that breaks this entire anonymization effort, and it’s worth knowing before you paste something private into chat again. Above the prompt, the reviewer sees a summary of the user’s memory. This is the same memory that makes ChatGPT know your profession, roughly where you live, and what you’re working on. Filters cut names from the question content, but context added from memory appears on screen along with it.
Asked directly whether it ever clearly communicated that human contractors might read prompts, OpenAI didn’t answer directly. The company’s public materials describe human review mainly in the context of terms-of-service violations and safety issues, not routine model training.
Where to disable it and what it won’t undo
The setting is called “Improve the model for everyone” and you’ll find it in Settings, in the Data Controls section. The toggle needs to be switched off. In the mobile app: menu, your profile, Data Controls. The setting is tied to your account, so it works across all devices at once, and also covers Codex if you use it as part of your personal plan.
And here’s the catch that isn’t talked about loudly. This only works going forward. Conversations that already entered the pool stay in the pool. Changing the setting today doesn’t withdraw anything you’ve written over the past two years.
It’s enabled by default on Free, Plus and Pro accounts. Disabled by default on Business, Enterprise, Edu plans and in the API. A separate path is temporary chats, which don’t go to training and disappear from OpenAI’s systems after thirty days. Your conversation history remains intact regardless of what you do with this toggle - disabling training doesn’t delete your chats and doesn’t break anything in functionality.
How others do it
Anthropic confirms it also uses human review for Claude, but claims this applies to users who opted in themselves by checking an option to help improve models. Google reportedly communicates human review of conversations in plain text. So the practice is industry-wide and isn’t a scandal in itself. The scandal, if any, is the gap between what people expect and what they consent to by default.
Google · Your sourcesQuantslant higher in your Google - one clickAdd to preferred sources →Who this really affects
The average user asking for a soup recipe isn’t affected. This affects three groups, and it’s worth recognizing yourself in them.
First: freelancers and small businesses who paste client materials into ChatGPT - contracts, correspondence, spreadsheet data. If you’re doing this on a Plus account with default settings, you’re formally and practically sending someone else’s data into a process where a stranger on contract might read it. For most industries, this is a conversation you don’t want to have with a client after the fact. The solution is cheap: disable the toggle or switch to a business plan, where it’s disabled from the start.
Second: people who treat ChatGPT like a diary or therapist. This isn’t about any law, just an informed decision. It’s worth making before you write the next message, not after reading the next leak.
Third: everyone who has memory enabled and never looked at it. Take a look. This is the same list the reviewer sees.
This whole story comes down to a sentence I’ve repeated here for a long time, except this time it has a price expressed in dollars per hour: in the free and cheap plan you don’t pay with money, you pay with text. What’s new is that now we know someone on the other side is reading that text.
Facts, quotes and numbers verified September 16, 2026. Sources: 404 Media investigation “Inside Project Lily”, Android Headlines coverage, Tom’s Guide guide, and official OpenAI Data Controls FAQ.
More on this from QUANTSLANT



 benchmarks·Qwen 27B: Style Training Changed AI Behavior UnexpectedlyTraining Qwen 27B only on Korean response style changed how often it said "I don't know" and volunteered information - behaviors the training never targeted.