Claude vs GPT-6: Polish Text Costs 56% More Tokens
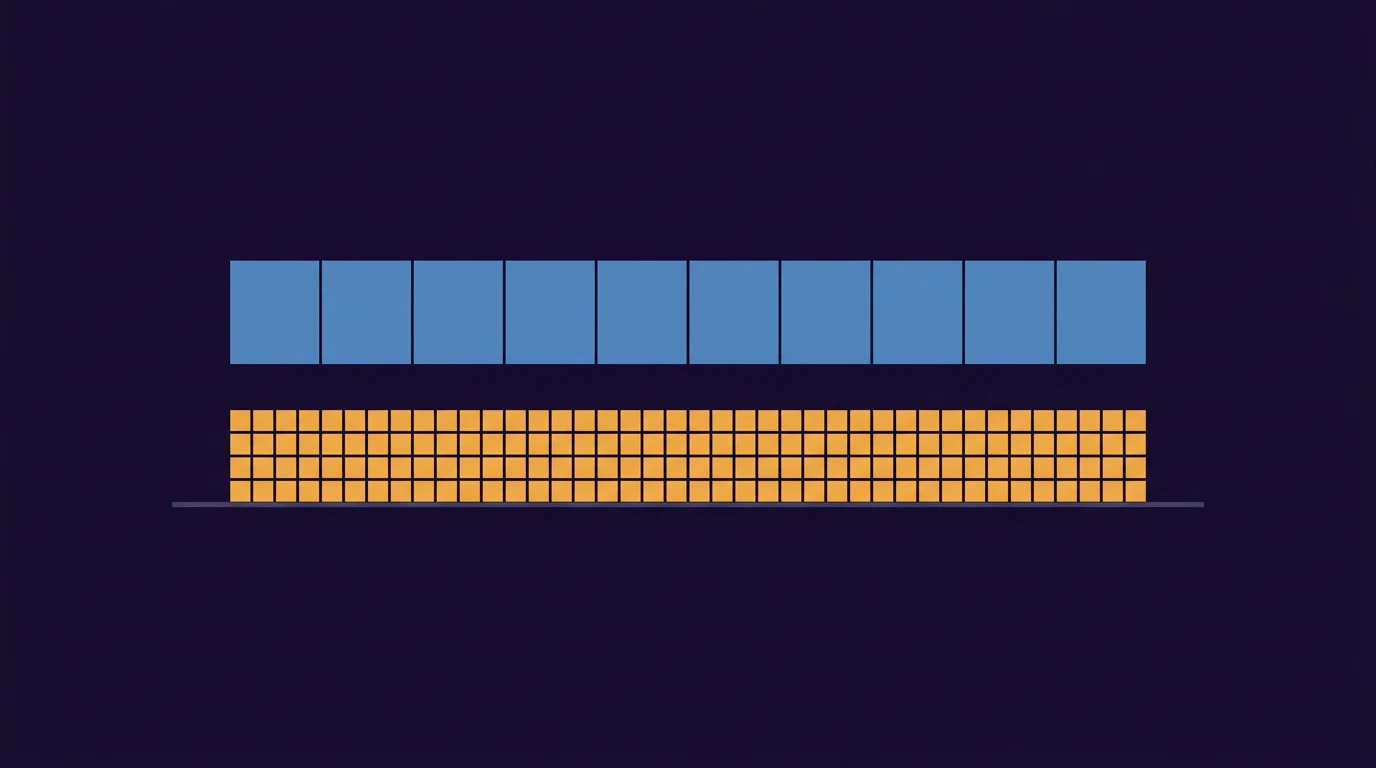
The same text takes 2,466 tokens in GPT-6 Astra but 3,859 in Claude Fable 5.1. We measured eight models to show what this means for your API bill.
Update (9 Nov 2026): Claude Fable 5.2 and Mythos 5.2 are out - prices, access and benchmarks are in my Claude Fable 5.2 guide.
👁 113 reads
A model’s pricing tells you the cost per million tokens. It doesn’t tell you how many tokens your text will consume, and that depends on how the model splits your language into chunks. We tested this the simplest way possible: we sent the same fragment of text - 7,843 characters, roughly 1,350 words, in Polish - to eight models with a one-token output limit and read the input token count from the API usage field. Total cost of the test: a few cents.
| Model | Tokens for same text | Characters per token | vs. GPT-6 Astra |
|---|---|---|---|
| GPT-6 Astra | 2,466 | 3.18 | 0% |
| GPT-5.6 Sol | 2,466 | 3.18 | 0% |
| Grok 4.6 | 2,489 | 3.15 | +1% |
| DeepSeek V4 Pro | 2,599 | 3.02 | +5% |
| Kimi K3 | 3,355 | 2.34 | +36% |
| Claude Sonnet 5 | 3,857 | 2.03 | +56% |
| Claude Fable 5.1 | 3,859 | 2.03 | +56% |
| Gemini 3.8 Flash | no data: API did not return usage with one-token limit | ||
Two tokenizer camps
The results fall into two groups. OpenAI, xAI and DeepSeek models fit around 3.1 characters of Polish text into one token. Anthropic and Kimi models split more densely: Claude needs 56 percent more tokens for the same text, Kimi 36 percent more. Both OpenAI models gave identical results, confirming that Astra uses the same tokenizer as the 5.6 line.
For English these differences are smaller, because all tokenizers were trained most heavily on English. Polish, with its inflections and diacritics, is a useful proxy for heavily inflected non-English languages - and you pay for inefficient tokenization with every request.
What this means for your bill
GPT-6 Astra and Claude Fable 5.1 have identical pricing: $10 per million input tokens. But for the same Polish text, Claude counts 3,859 tokens while Astra counts 2,466. At the same rate, Fable input costs 56 percent more in practice. For a single query that’s fractions of a cent; for a thousand long documents per month it’s a difference you’ll see on your invoice.
This works the other way too, favoring cheaper models. Claude Sonnet 5 costs $2 per million input tokens, five times less than Astra, but the denser tokenizer reduces the real price advantage on Polish text from fivefold to roughly threefold. Comparing price lists alone leads to wrong conclusions if you don’t account for the tokenizer.
Google · Your sourcesQuantslant higher in your Google - one clickAdd to preferred sources →How to measure this yourself
You don’t need to guess. Just send your typical document to a model with a one-token output limit and read the input token count from the usage field. The cost of such a measurement is a fraction of a cent, and the result tells you more about your bill than a price table.
One caveat: we measured one fragment of one text. The proportions between tokenizers are stable because they result from their design, but exact numbers for your documents may differ slightly, especially for texts with lots of code, numbers or proper names. We ran this test in Polish; results for other non-English languages will vary but follow similar patterns.
More on this from QUANTSLANT



 benchmarks·GPT-6 Astra for Coding: What the Benchmarks Show (and Hide)Terminal-Bench, DeepSWE, and FrontierCode results show GPT-6 Astra's mixed performance against Claude Fable 5.1 and Opus 5 - and where the 5x price difference matters.