Gemini 4 Argon Test: 23 Tasks vs Opus 5.5 and GPT-6 Astra
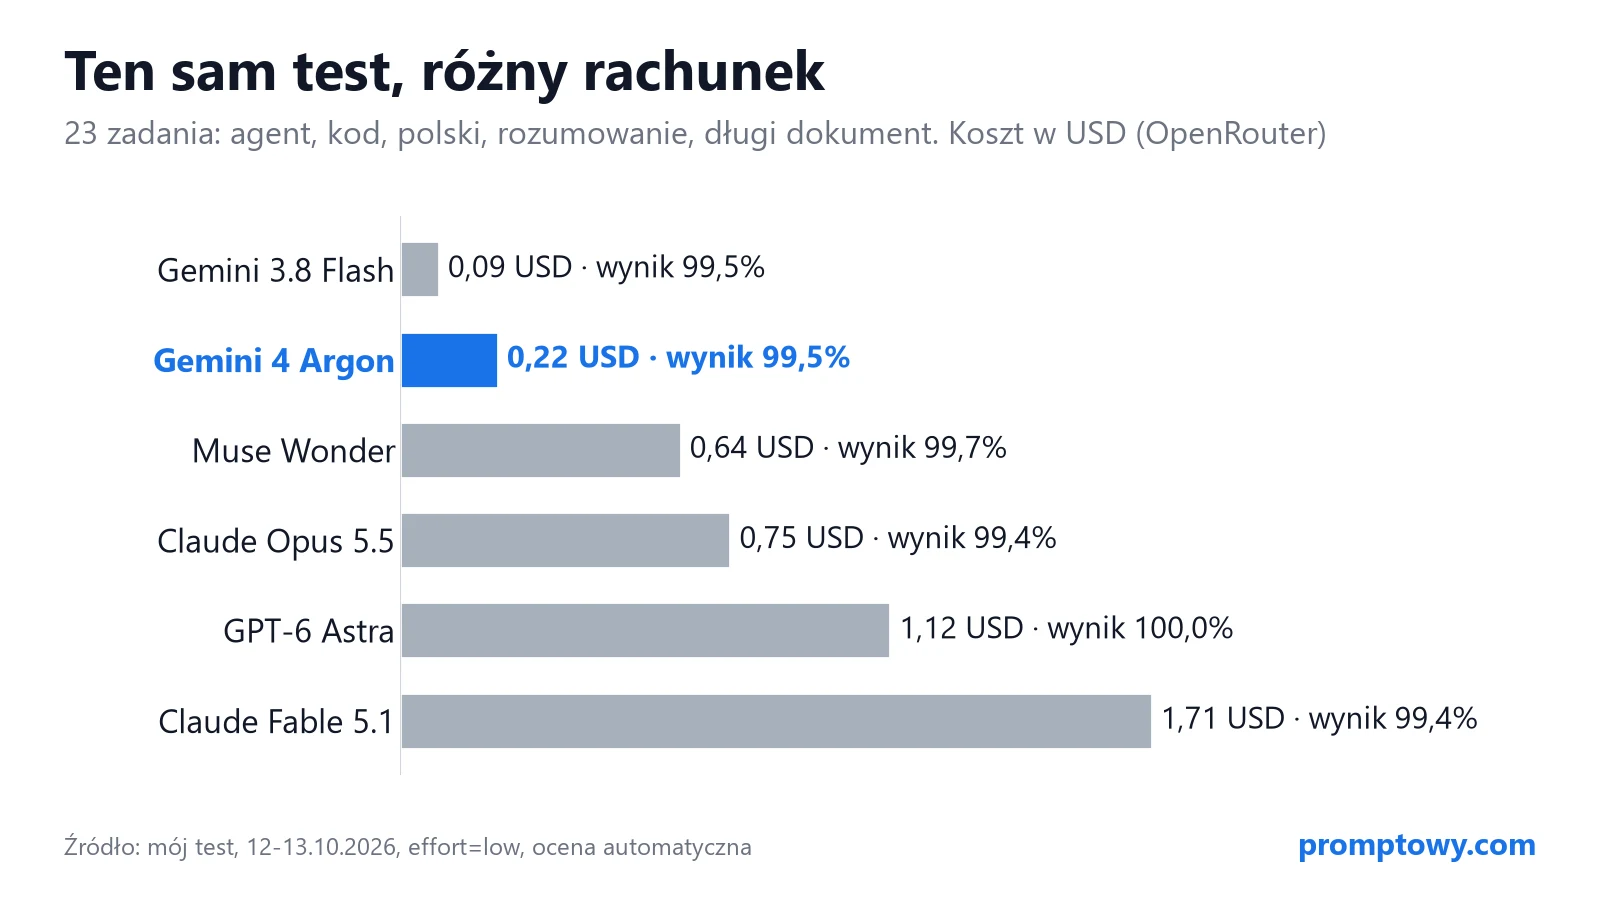
I tested Gemini 4 Argon across 23 tasks against Opus 5.5 and GPT-6 Astra. It scored 99.5% for $0.22 with the fastest completion time.
Update (9 Nov 2026): Claude Fable 5.2 and Mythos 5.2 are out - prices, access and benchmarks are in my Claude Fable 5.2 guide.
👁 126 reads
On the evening of October 13, 2026, roughly half an hour after Google opened Gemini 4 Argon to paying customers, I ran it through the exact same battery of 23 tasks assigned a day earlier to Muse Wonder, Claude Opus 5.5, Claude Fable 5.1, GPT-6 Astra, and Gemini 3.8 Flash. Argon scored 99.5%, cost $0.22, and finished faster than any competitor: 135 seconds for the complete run. Its only deducted point stemmed from an evaluation script bug, although a genuine issue surfaced just a few paragraphs down in the same draft. You can find model specs, pricing, and availability details in the guide to Gemini 4 Argon.
Test run: October 13, 2026, evening
- Model:
google/gemini-4-argonvia OpenRouter, low reasoning effort. - Rivals: identical 23 tasks, same codebase and configuration, evaluated on October 12 in the Muse Wonder benchmark.
- Automated evaluation: unit tests, tool call inspection, exact string matching. No AI judge. Every lost point was reviewed manually.
- Total test cost for Argon: $0.22 at introductory rates ($2/$10 per million tokens).
Benchmark results across all models
| Model | Score (23 tasks) | Cost | Total time |
|---|---|---|---|
| Gemini 4 Argon | 99.5% | $0.22 | 135 s |
| Muse Wonder | 99.7% | $0.64 | 165 s |
| Claude Opus 5.5 | 99.4% | $0.75 | 222 s |
| GPT-6 Astra | 100% | $1.12 | 200 s |
| Claude Fable 5.1 | 99.4% | $1.71 | 263 s |
| Gemini 3.8 Flash | 99.5% | $0.09 | 139 s |
The overall score represents the unweighted mean across all 23 tasks. For multi-part tasks, the percentage reflects the share of criteria met. Among flagship models, Argon was the cheapest: 3.4x cheaper than Claude Opus 5.5, 5x cheaper than GPT-6 Astra, and 2.9x cheaper than Muse Wonder. Only Gemini 3.8 Flash came in lower, sitting in a budget tier.
Tasks evaluated in the benchmark
| Category | Tasks | Evaluation method |
|---|---|---|
| Tool-calling agents (3) | Lisbon trip planning with 3 tools and price traps, overdue retail shoe return, EUR invoices converted at central bank rates with a simulated 503 outage on the initial request | Tool call correctness, tool selection, numerical output |
| Code generation (4) | Tax ID validation, interval merging, Polish working days accounting for the Christmas Eve holiday from 2025 onward, currency amounts spelled out in Polish words | 51 local unit tests |
| Polish language handling (4) | Correcting 10 grammatical errors, 3-point summary strictly under 60 words, social security appeal letter, declension of 10 complex proper nouns | Checklist criteria and exact string forms |
| Reasoning (11) | Combinatorics, calendar math, clock hands, knights and knaves puzzles | Exact match answers |
| Long context document (1) | 80 corporate board meeting minutes (158,111 characters in Polish), 5 questions, including an amended prior decision and an unmentioned event | Exact match answers |
Performance breakdown by category
| Category | Gemini 4 Argon | Claude Opus 5.5 | GPT-6 Astra |
|---|---|---|---|
| Agent | 100%, $0.025 | 100%, $0.091 | 100%, $0.100 |
| Code | 100%, $0.028 | 100%, $0.083 | 100%, $0.130 |
| Polish language | 97.2%, $0.022 | 96.4%, $0.110 | 100%, $0.108 |
| Reasoning | 100%, $0.044 | 100%, $0.114 | 100%, $0.084 |
| Long document | 100%, $0.103 | 100%, $0.355 | 100%, $0.695 |
Bold formatting highlights the top score per category, breaking ties with the lowest cost. The remaining models dropped marks elsewhere: Muse Wonder stumbled on code (98.4%, outputting a nonexistent Polish numeral construction), Gemini 3.8 Flash also dropped code points (96.9%, treating Christmas Eve as a holiday starting in 2024 instead of 2025), while Claude Fable 5.1 and Opus 5.5 lost points in Polish language tasks (96.4%, breaching the 60-word limit on the summary).
Speed and cost advantages
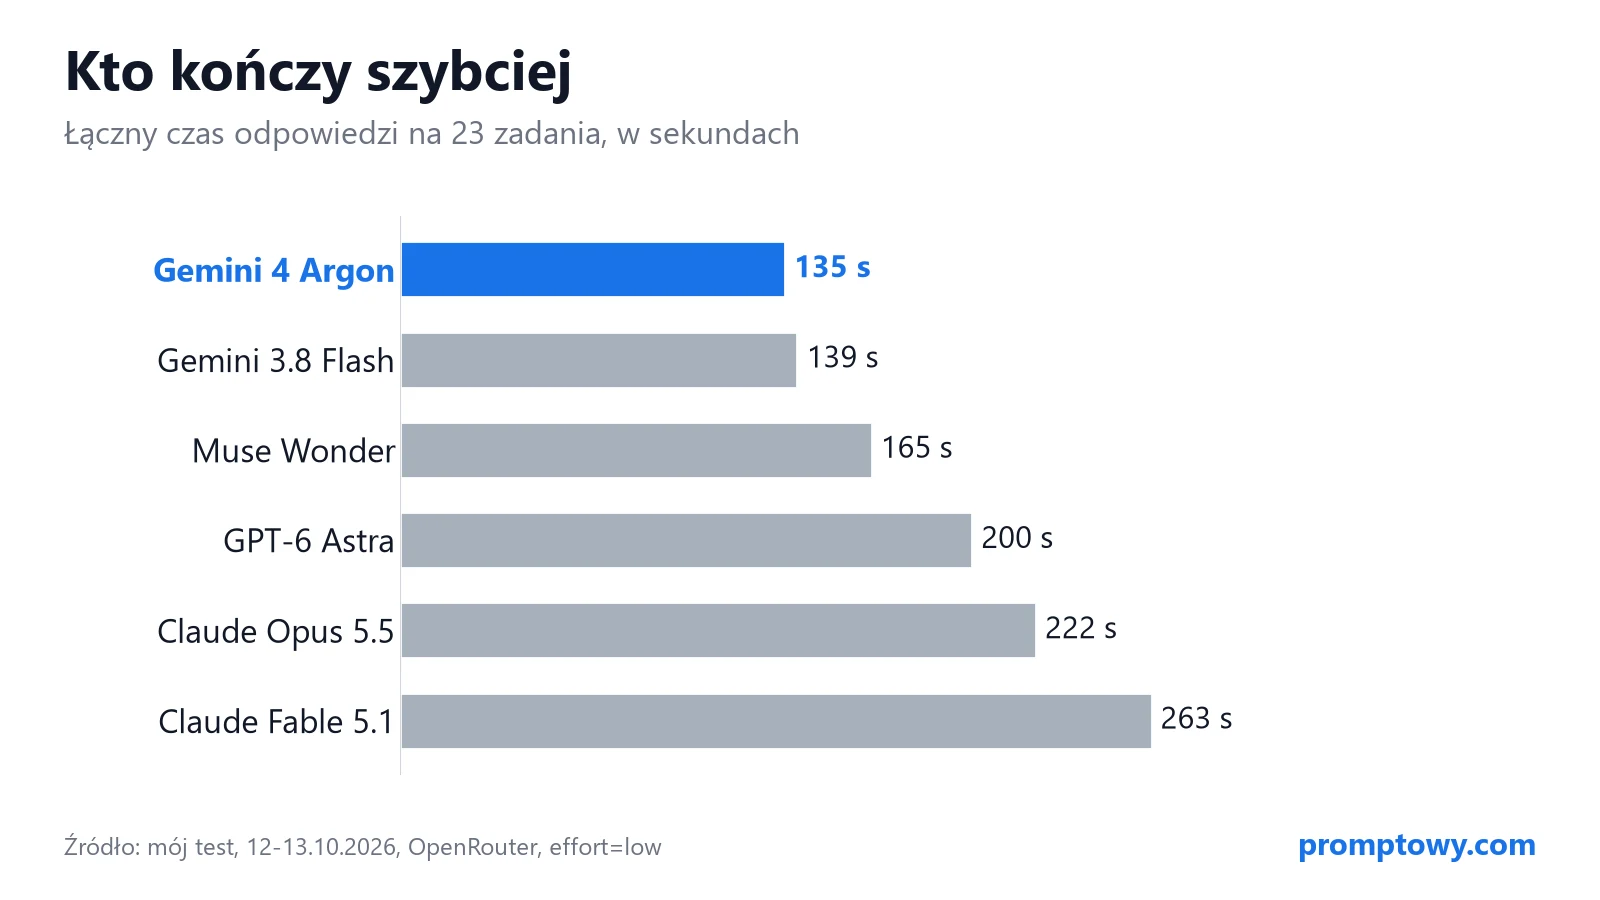
Argon produces concise responses without delay. At the low reasoning tier, OpenRouter reported zero reasoning tokens across the entire 23-task run, and the 10-error proofreading prompt returned in 2.6 seconds. In contrast, Muse Wonder spent 636 reasoning tokens on the travel task alone. Key observations:
- Lisbon itinerary: 4 tool calls across 2 turns, dodging both traps (an overly early flight and a poorly rated hotel), calculating roughly $448 for the budget, and scheduling a museum visit due to an 80% rain forecast. Matches the competition, but at a cost of only $0.011.
- Retail return request: Correctly targeted the right order item, rejected the return, and explained to the customer that 32 days had elapsed past the 30-day window.
- EUR invoices: Successfully retried after the simulated 503 error, excluded paid invoices, and calculated the correct total.
- Long document processing: 5 out of 5 correct answers in 4.5 seconds for $0.10. It noted that a warehouse footprint had been revised to 6,200 m2 and answered that no TikTok campaign existed. Only GPT-6 Astra answered faster (3.5 s), but cost $0.69.
Token efficiency is another major factor on non-English text. Those 158,111 Polish characters converted to 51,482 tokens for Argon versus 87,675 for Claude, a 70% overhead. Combined with cheaper base pricing, querying 80 meeting transcripts cost $0.10 on Argon, $0.19 on Muse Wonder (46,929 tokens at $4 per million), $0.35 on Opus 5.5, $0.69 on Astra, and $0.88 on Fable 5.1.
The legal appeal test: false penalty and real hallucination
The automated script initially awarded Argon 8 out of 9 points on a legal disability benefit appeal letter, flagging a missing recipient line for the regional court. Inspecting the raw text showed the recipient was present; the model had simply used standard Polish genitive case phrasing rather than the nominative string expected by the script. Correcting that manual false negative brings Argon to 100%, matching GPT-6 Astra. The automated 99.5% is kept in the comparison table to maintain uniform scoring rules across all runs.
The draft handled procedural specifics well, noting the prerequisite objection step and calculating the statutory deadline around weekend and holiday closures to land on November 2, 2026. However, an unprompted hallucination appeared in the factual narrative. Given only a basic prompt stating that an evaluator overlooked 2026 cardiology treatment records, Argon fabricated specific physical symptoms and misconduct accusations against the physician (translated from the tested Polish output):
“The symptoms of the condition, such as rapid fatigue, exertional dyspnea, blood pressure spikes, and chest pain, prevent me from functioning normally in everyday life (…)”
“The certifying physician, when issuing the decision, conducted the examination in a perfunctory manner (…)”
Opus 5.5 also suggested fatigue and shortness of breath, but wrapped them inside placeholder brackets for the user to verify. Argon inserted them directly as established facts. In formal filings subject to evidentiary review, fabricating medical claims is dangerous. Any administrative drafts created by Argon require line-by-line review.
Pricing changes after December 1
The launch pricing of $2 / $10 per million tokens runs through November 30, 2026. Starting December 1, Argon shifts to $4 / $20, bringing its listed rates level with Opus 5.5 and Muse Wonder. Applying those base rates roughly doubles the cost of this suite:
| Model | Price per 1M tokens (input / output) | 23-task suite cost |
|---|---|---|
| Gemini 4 Argon (through Nov 30) | $2 / $10 | $0.22 |
| Gemini 4 Argon (from Dec 1) | $4 / $20 | approx. $0.45 ($0.22 x 2) |
| Muse Wonder | $4 / $20 | $0.64 |
| Claude Opus 5.5 | $4 / $20 | $0.75 |
| GPT-6 Astra | $10 / $50 | $1.12 |
| Claude Fable 5.1 | $10 / $50 | $1.71 |
| Gemini 3.8 Flash | $0.75 / $3.75 | $0.09 |
Even with list prices equalized, Argon remains roughly 1.7x cheaper than Opus 5.5 on this benchmark. That delta stems from direct output without excess hidden thinking tokens and a denser tokenizer on non-English text. Context caching rates also adjust from $0.10 to $0.20 per million tokens.
Test caveats and scope
- Effort=low. All models were tested on their lowest reasoning tier to measure cost-efficient throughput. Google’s official benchmarks use maximum reasoning effort, reflecting different operating conditions.
- Single test pass. 23 distinct tasks, executed once. Single-point discrepancies reflect margin of error rather than conclusive capability gaps.
- Test execution dates. Competing models ran on October 12; Argon ran on October 13 shortly after public API launch. Prompts and evaluation code were identical, but network conditions and server load varied.
- Performance ceiling. All leading models clustered between 99% and 100%. This suite evaluates latency, cost efficiency, and specific failure modes rather than frontier-level puzzle solving.
- Automated scoring. Automated evaluations focus on factual matching and structured checks. The appeal letter shows that scripts can misread inflected language, which is why all failed assertions were inspected manually.
- OpenRouter routing. Evaluated via OpenRouter rather than direct Google Cloud endpoints. Model weights and pricing match, but direct API infrastructure was not measured here.
Verdict
For standard production workloads, Gemini 4 Argon delivers results comparable to Opus 5.5, Astra, and Fable 5.1 at lower latency and lower cost. Through November 30, it is the cheapest flagship tested, and its tokenizer advantages keep it economical on multilingual text even under standard December rates. Its main weaknesses lie in unsubstantiated factual embellishments in structured legal drafting and softer prose output: in a separate blind Polish creative writing benchmark, it took 8th place with 81.8 points, trailing Claude Opus 5.5 at 90.1 points (detailed in the Gemini 4 Argon Polish language analysis). This evaluation reflects a single run conducted on October 13, 2026.
Frequently asked questions
Is Gemini 4 Argon better than Claude Opus 5.5?
Across these 23 structured tasks, performance was practically identical: 99.5% versus 99.4%. Argon was 3.4x cheaper and noticeably faster, while Opus 5.5 showed stronger nuances in non-English prose generation.
What is Gemini 4 Argon’s API pricing?
Through November 30, 2026, pricing is set at $2 per million input tokens and $10 per million output tokens. On December 1, pricing shifts to $4 input and $20 output.
How was Argon accessed for this benchmark?
The tests were conducted using OpenRouter (google/gemini-4-argon), which was operational from Poland on October 13, 2026.
Sources
- Benchmark run via OpenRouter: Gemini 4 Argon on Oct 13, 2026; competing models on Oct 12, 2026; 23 tasks, effort=low, automated scoring with manual verification
- OpenRouter: Gemini 4 Argon details and context limits
- Gemini API: Official pricing documentation
- Google: Gemini 4 Argon announcement (Oct 13, 2026)
- Google DeepMind: Gemini 4 Argon evaluation report
More on this from QUANTSLANT



 news·Liquid AI Releases LFM2.5-24B-A2B: Fast On-Device Agent ModelLiquid AI has released LFM2.5-24B-A2B on Hugging Face, combining 24B parameters with 2B active activation for fast, private on-device agents.