Imagen 3 vs Imagen 3 Fast vs DALL-E 3: 6-Task Test
Three image generators, six tasks, identical prompts. Non-English diacritics are no longer a problem, counting apples still is.
👁 116 reads
The question I get most often about image generators is: which one is best right now? The answer “it depends” is true and useless, so I did what I usually do: same prompts to three models, one run each, no cherry-picking the prettiest from multiple attempts. What came out came out, and everything is below side by side.
Models: Imagen 3 and Imagen 3 Fast from Google (both from June) and DALL-E 3 from OpenAI (from April). Anticipating the question: there simply is no newer image model from OpenAI, I checked the model list on September 4 and the freshest entry from that company is exactly this one. I chose six tasks so that each measures one specific skill, not general “prettiness”.
Task 1: Non-English text with diacritics
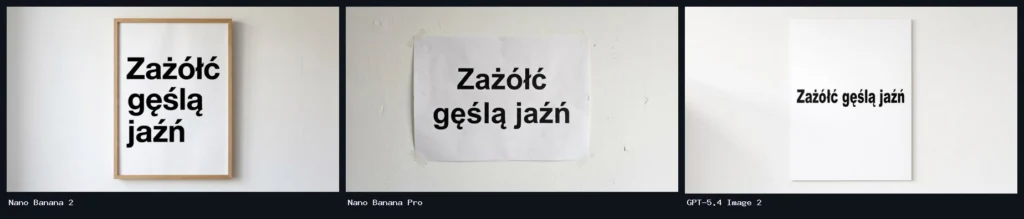
A year ago this was a test that every generator failed: the letters ą, ę, ł, ś, ź would land as random strokes or disappear. Today all three models wrote “Zażółć gęślą jaźń” flawlessly, with every diacritic in place. The differences are purely stylistic: Google added a frame and tape, OpenAI made a bare sheet. This problem can be considered solved.
Task 2: exactly four apples and two pears
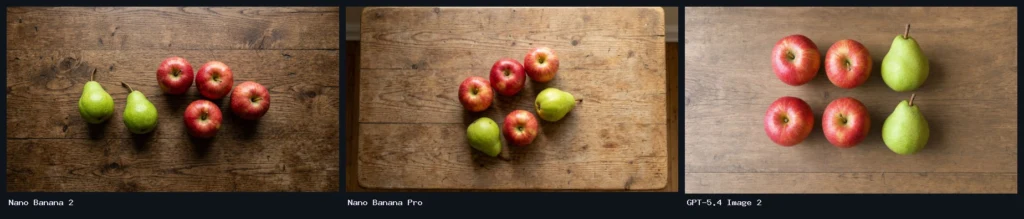
Counting is still a weak point. Imagen 3 Fast drew a fifth apple. Imagen 3 and DALL-E 3 counted correctly, with OpenAI’s model arranging the fruit in a rigid two-by-three grid, as if to make the task easier, while Google’s model scattered them naturally and still didn’t make a mistake. If an image needs to show a specific number of anything, Google’s cheaper model is out.
Task 3: hands
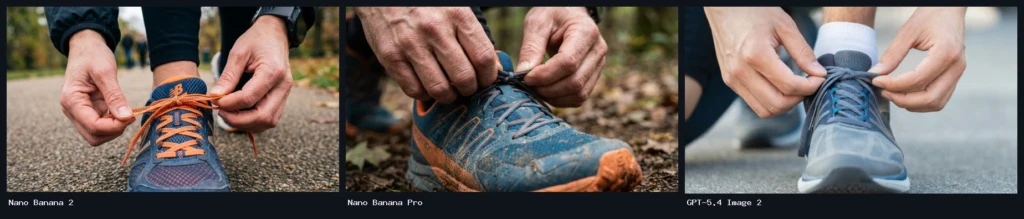
A classic test where generators used to draw a sixth finger. In all three images the hands have the correct number of fingers and a sensible grip on the lace. Imagen 3 gave the most photographic frame with mud on the shoe, DALL-E 3 the cleanest but somewhat plastic. At this resolution I see no anatomical errors in any of them.
Task 4: Warsaw, tram, rain, dusk
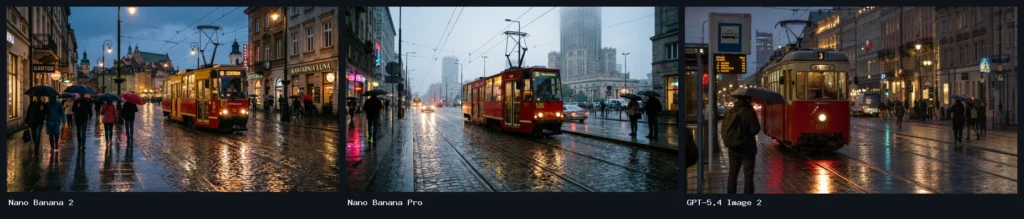
Here you can see what the models know about Warsaw. Imagen 3 put the Palace of Culture in the background and an articulated tram in Warsaw colors, a scene anyone who’s been to the capital will recognize. Imagen 3 Fast gave an old-town-style street with readable Polish signs. DALL-E 3 generated a vintage car with a destination board and a stop pole, correctly, but without a landmark. All three maintain light, wet pavement and reflections at a level that was unattainable two years ago.
Task 5: flat illustration, minimalism, no text
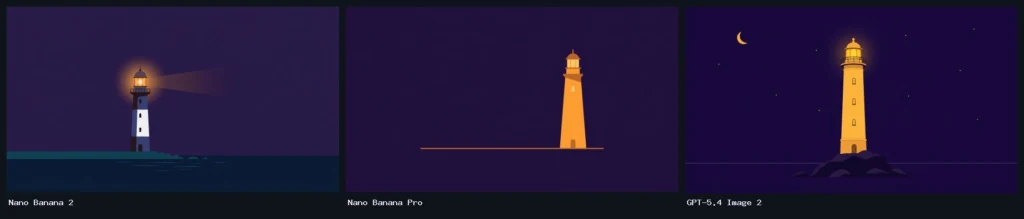
The prompt said explicitly: one lighthouse, thin horizon line, lots of empty space, no text. Only Imagen 3 executed it literally and produced the cleanest illustration in the entire test. Imagen 3 Fast added a sea and rocks, DALL-E 3 threw in a moon, stars and a rocky island. Pretty, but nobody asked for it. In editorial work, where an illustration needs to match an established style, obedience to the prompt is more important than invention.
Task 6: diagram with Polish labels
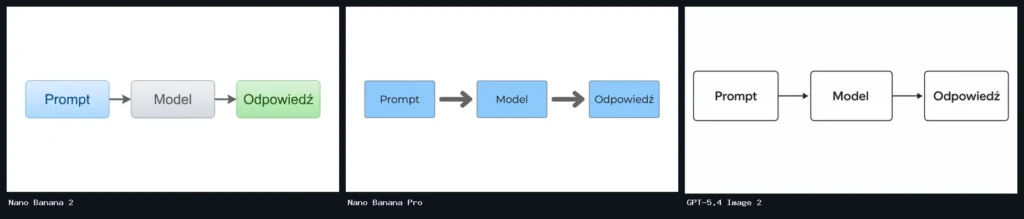
Three boxes, two arrows, labels “Prompt”, “Model”, “Odpowiedź“. All three models did it correctly, with the diacritic in the last word. They differ only in style: Google colors the boxes, OpenAI gives black outlines on white. Diagrams with short text are now safe with any of them.
Generation time
| Model | Fastest | Slowest | Typical |
|---|---|---|---|
| Imagen 3 Fast | 8 s | 17 s | around 12 s |
| Imagen 3 | 19 s | 28 s | around 21 s |
| DALL-E 3 | 59 s | 97 s | around 76 s |
OpenAI’s model was four to eight times slower than both Google models. For one image it doesn’t matter, for a series of several dozen illustrations it’s the difference between fifteen minutes and an hour.
Verdict
Imagen 3 won this test: it counted the fruit, obeyed the minimalism instruction, gave the most recognizable Warsaw and made no errors in text. Imagen 3 Fast is the fastest and sufficient for most tasks, but not where precise object count matters. DALL-E 3 makes correct, clean images, just very slowly and with a tendency to add decorations nobody asked for.
One caveat: six tasks and one run each is reconnaissance, not a statistical measurement. It shows what came out on the first try, because that’s exactly how most people use these tools. Current pricing for all three models is on their pages at OpenRouter and changes more often than I could update them here.
Google · Your sourcesQuantslant higher in your Google - one clickAdd to preferred sources →Update September 5: longer text on poster
After the first test I got a question whether one sentence with diacritics was too little. So I tested a poster with a headline and four lines in Polish: “Cztery zasady dobrego promptu” (“Four rules of a good prompt”), and below “Podaj cel i odbiorcę” (“State goal and audience”), “Dołącz przykład” (“Attach example”), “Określ długość i format” (“Specify length and format”), “Sprawdź źródła, zanim uwierzysz” (“Check sources before you believe”). Eight words with diacritics, including “źródła” and “długość”, which like to fall apart.
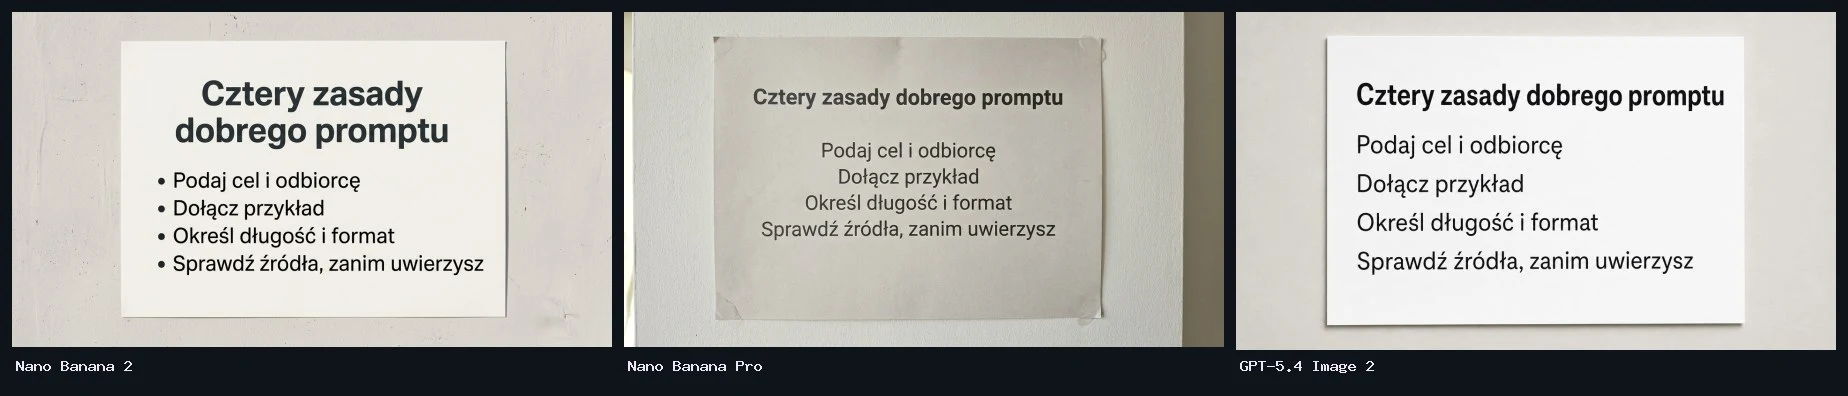
All three models rendered the full text without a single error in letters and diacritics. Imagen 3 Fast added bullet points I didn’t ask for, Imagen 3 centered the text on a crumpled sheet, DALL-E 3 aligned it left on a clean sheet. Times as before: 8, 20 and 77 seconds. The conclusion from the first test only strengthened: Polish text in images, even longer text, has stopped being an obstacle for any of these three generators.
More on this from QUANTSLANT


 benchmarks·GPT-6 Astra Hallucination Test: Fake Facts vs Real OnesWe asked four top AI models about things that don't exist. A year ago, they would have invented biographies. Now? The results surprised us.