Wan 2.2 on RTX 4090: timings, VRAM and four test clips
My four-clip Wan 2.2 TI2V 5B test: RTX 4090 timings, memory use, visible mistakes and the limits of applying these results to another GPU.
👁 311 reads
Wan 2.2 runs locally on a single 24 GB card: on my RTX 4090 the TI2V 5B version made a 5-second 1280×704 clip in about 4 minutes, with recorded total VRAM peaks shown below and roughly 0.02 kWh of GPU energy during a warm run. It is available under Apache 2.0. The availability comparison with Wan 3.0 below is a historical October record. I use the tested workflow for backgrounds, sketches and b-roll with little motion; precise physical actions need shot-by-shot checking regardless of the service. Below are four unedited clips from my September 26, 2026 test, with timings, memory use and the visible errors.
TI2V 5B is the Wan 2.2 version that fits a gaming GPU
Wan 2.2 is a family of open video models from Alibaba’s Wan-AI team, released under the Apache 2.0 license. As of October 29, 2026, the newest uploads in the Wan-AI Hugging Face organization are still Wan 2.2 variants (Wan2.2-Animate-2, August 2026); Wan 3.0 appears here as a hosted-service comparison, not as a claim that no downloadable weights can exist elsewhere. Larger variants (14 billion parameters) need significantly more memory than a typical gaming card has. The TI2V 5B version has 5 billion parameters and generates video from text alone, or from a starting image plus text. It runs on a single 24 GB card. I used ready-made files prepared by the ComfyUI team:
- model
wan2.2_ti2v_5B_fp16.safetensors- 10.0 GB, - text encoder
umt5_xxl_fp8_e4m3fn_scaled.safetensors- 6.7 GB, - VAE
wan2.2_vae.safetensors- 1.4 GB.
The files go into the models/diffusion_models, models/text_encoders, and models/vae folders in ComfyUI. For how to set up ComfyUI itself, see the guide ComfyUI from scratch.
About 4 minutes per clip once the model is loaded
Each clip: 1280×704, 121 frames at 24 fps (5.04 s), 20 steps, CFG 5, uni_pc sampler, shift 8. These are the settings from the official ComfyUI template for Wan 2.2 5B. Card: RTX 4090 24 GB, Windows 11, ComfyUI 0.37.
| Clip | Generation time | VRAM peak | Average power draw |
|---|---|---|---|
| Coffee (first, with model loading) | 574 s | 23.6 GB | 141 W |
| Tram in rain (first in second series) | 592 s | 23.6 GB | 146 W |
| Llama in meadow | 239 s | 23.9 GB | 312 W |
| 2D animation with cat | 232 s | 23.4 GB | 319 W |
The first clip in a series takes over twice as long because the model loads from disk into memory. Subsequent ones take about 4 minutes. The VRAM peak includes about 3.4 GB occupied earlier by the system and browser, so a simple subtraction gives roughly 20 GB. That estimate does not isolate the model precisely or establish its minimum VRAM. This run does not establish compatibility or speed on 12-16 GB cards. Offloading can reduce GPU memory pressure, but the workflow, system RAM and other components still matter.
Four clips: rain works, pouring liquid does not
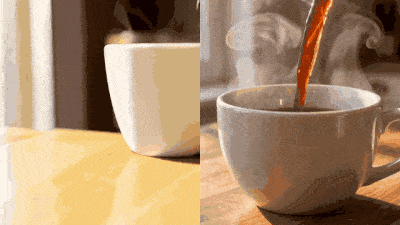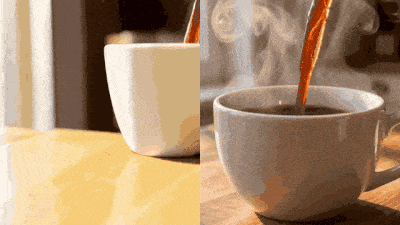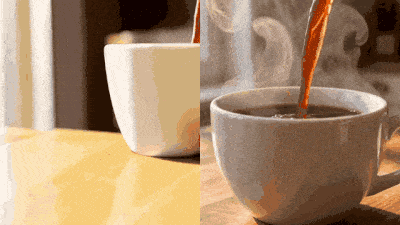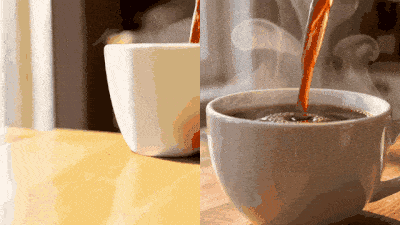
1. Coffee being poured into a cup
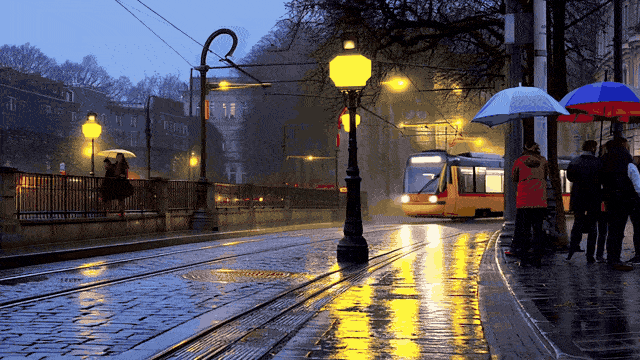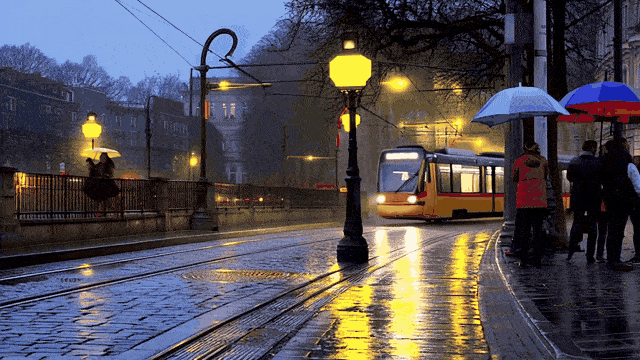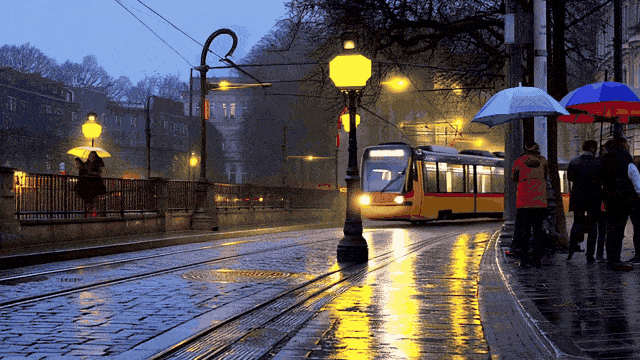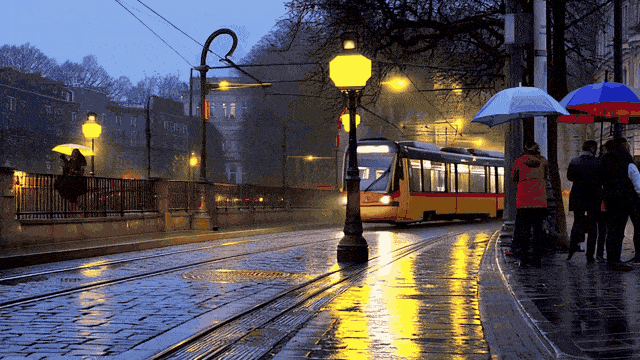
2. Tram in the rain
3. Llama in a mountain meadow
4. 2D animation: working at night with a cat
The pattern is clear: the less movement and physics, the better. “Tripod” shots with movement in the background (rain, tram, leaves) come out convincingly. Precise actions like pouring liquid or a specific animal gesture, the model simplifies or distorts.
Local Wan 2.2 costs electricity, cloud models cost per clip
| Wan 2.2 5B local | Paid generators (Kling, Veo, Wan 3.0) | |
|---|---|---|
| GPU energy / quoted service price per clip | about 0.02 kWh of electricity (315 W card for 4 min) | $0.18-0.52 per 4-6 s clip at 480p-720p in my AI Video Arena |
| Time | ~4 min | depends on the provider’s queue |
| Resolution | 1280×704, 24 fps | up to 1080p and more |
| Audio | none | yes in some models |
| Privacy | local generation; check any network-enabled nodes | prompts and images go to server |
| Limits | no daily limits | credit limits and content filters |
Cloud prices change often; my current comparison is in the AI video generator ranking. I find the local workflow useful for batches of working shots, backgrounds and editing material. Whether it is cheaper depends on the electricity tariff, hardware costs, discarded generations and the service being compared.
A Python script that turns one prompt into an MP4
The model files will be downloaded by the installation script from the ComfyUI guide with the -Models wan option. For generation itself, I prepared a script that sends a prompt to ComfyUI, waits for frames, and assembles them into MP4 via ffmpeg. You specify length in seconds, and the script converts it to the number of frames in the format Wan requires (4n+1). I tested it on September 26, 2026 on a short test clip: 2 seconds at 640×352, 49 frames, finished MP4 file.
- Download: generuj-wideo.py (6 KB) or all 5 scripts in one ZIP file (15 KB).
- 5 s 720p clip:
python generuj-wideo.py "a yellow tram passing a rainy street at dusk, static camera" - Faster preview:
--sekundy 3 --szer 960 --wys 544 --kroki 12(the flag names are Polish: seconds, width, height, steps). For MP4 you need ffmpeg (winget install Gyan.FFmpeg), without it you’ll get PNG frames.
Before you run any script from the internet, read it. It runs with your permissions. That’s why the full code is below, unshortened, with comments. The scripts are under MIT license: you can modify and use them in your company too.
"""
generuj-wideo.py - clip from Wan 2.2 TI2V 5B via local ComfyUI (quantslant.com/wan-2-2-local-gpu-test/)
Author: Piotr Olszewski, quantslant.com. Script license: MIT. Tested 26.09.2026: ComfyUI 0.37, RTX 4090.

Requires: running ComfyUI (http://127.0.0.1:8188) with Wan 2.2 5B files
(instaluj-comfyui.ps1 -Modele wan) and ffmpeg in PATH to assemble MP4 (winget install Gyan.FFmpeg).
Without ffmpeg you get PNG frames only. Python 3.9+ standard library only.

Examples:
  python generuj-wideo.py "a yellow tram passing a rainy street at dusk, static camera, realistic"
  python generuj-wideo.py "flat 2D animation of a cat walking across a desk" --sekundy 3 --szer 960 --wys 544

On RTX 4090: 5 s at 1280x704 takes ~4 minutes (first clip longer - loading 18 GB from disk).
Model handles static camera and background movement best, struggles with precise physics (pouring, gestures).
"""
import argparse, json, os, random, shutil, subprocess, sys, tempfile, time, urllib.parse, urllib.request, uuid

FPS = 24
NEG = "blurry, distorted, low quality, jitter, watermark, text, subtitles, static image, deformed hands, extra limbs"


def graf(polecenie, szer, wys, klatki, kroki, seed, prefiks):
    # equivalent of official ComfyUI template "Wan 2.2 5B text to video"
    return {
        "1": {"class_type": "UNETLoader", "inputs": {"unet_name": "wan2.2_ti2v_5B_fp16.safetensors", "weight_dtype": "default"}},
        "2": {"class_type": "CLIPLoader", "inputs": {"clip_name": "umt5_xxl_fp8_e4m3fn_scaled.safetensors", "type": "wan", "device": "default"}},
        "3": {"class_type": "VAELoader", "inputs": {"vae_name": "wan2.2_vae.safetensors"}},
        "4": {"class_type": "CLIPTextEncode", "inputs": {"clip": ["2", 0], "text": polecenie}},
        "5": {"class_type": "CLIPTextEncode", "inputs": {"clip": ["2", 0], "text": NEG}},
        "6": {"class_type": "ModelSamplingSD3", "inputs": {"model": ["1", 0], "shift": 8.0}},
        "7": {"class_type": "Wan22ImageToVideoLatent", "inputs": {"vae": ["3", 0], "width": szer, "height": wys, "length": klatki, "batch_size": 1}},
        "8": {"class_type": "KSampler", "inputs": {"model": ["6", 0], "seed": seed, "steps": kroki, "cfg": 5.0, "sampler_name": "uni_pc", "scheduler": "simple",
                                                    "positive": ["4", 0], "negative": ["5", 0], "latent_image": ["7", 0], "denoise": 1.0}},
        "9": {"class_type": "VAEDecode", "inputs": {"samples": ["8", 0], "vae": ["3", 0]}},
        "10": {"class_type": "SaveImage", "inputs": {"images": ["9", 0], "filename_prefix": prefiks}},
    }


def api(serwer, sciezka, dane=None):
    req = urllib.request.Request(serwer + sciezka, data=json.dumps(dane).encode() if dane is not None else None,
                                 headers={"Content-Type": "application/json"})
    return json.load(urllib.request.urlopen(req, timeout=60))


def main():
    a = argparse.ArgumentParser(description="Video clip from Wan 2.2 5B via local ComfyUI")
    a.add_argument("polecenie", help="shot description (best in English, with camera description)")
    a.add_argument("--sekundy", type=float, default=5.0, help="clip length (default 5 s)")
    a.add_argument("--szer", type=int, default=1280); a.add_argument("--wys", type=int, default=704)
    a.add_argument("--kroki", type=int, default=20)
    a.add_argument("--seed", type=int, default=None)
    a.add_argument("--serwer", default="http://127.0.0.1:8188")
    a.add_argument("--wyjscie", default="wideo")
    x = a.parse_args()
    if x.szer % 32 or x.wys % 32:
        a.error("width and height must be multiples of 32 (e.g. 1280x704, 960x544)")
    klatki = int(round(x.sekundy * FPS / 4)) * 4 + 1          # Wan requires length 4n+1
    try:
        api(x.serwer, "/system_stats")
    except Exception as e:
        sys.exit(f"Cannot connect to ComfyUI at {x.serwer} ({e}). Run start-comfyui.bat.")
    seed = x.seed if x.seed is not None else random.randint(1, 2**31)
    prefiks = f"wan_{uuid.uuid4().hex[:8]}"
    print(f"Generating {klatki} frames ({klatki / FPS:.1f} s) at {x.szer}x{x.wys}, seed {seed}...")
    t0 = time.time()
    pid = api(x.serwer, "/prompt", {"prompt": graf(x.polecenie, x.szer, x.wys, klatki, x.kroki, seed, prefiks), "client_id": str(uuid.uuid4())})["prompt_id"]
    while True:
        h = api(x.serwer, f"/history/{pid}")
        if pid in h:
            break
        print(f"r  running... {time.time() - t0:.0f} s", end="", flush=True)
        time.sleep(2)
    print()
    wynik = h[pid]
    if wynik.get("status", {}).get("status_str") != "success":
        sys.exit("ComfyUI error: " + json.dumps(wynik.get("status", {}), ensure_ascii=False)[:600])
    imgs = sorted([o for v in wynik["outputs"].values() for o in v.get("images", [])], key=lambda o: o["filename"])
    os.makedirs(x.wyjscie, exist_ok=True)
    tmp = tempfile.mkdtemp(prefix="wan_")
    for i, img in enumerate(imgs):
        q = urllib.parse.urlencode({"filename": img["filename"], "subfolder": img.get("subfolder", ""), "type": img.get("type", "output")})
        with urllib.request.urlopen(f"{x.serwer}/view?{q}", timeout=60) as r, open(os.path.join(tmp, f"{i:04d}.png"), "wb") as f:
            shutil.copyfileobj(r, f)
    czas = time.time() - t0
    nazwa = os.path.join(x.wyjscie, f"wan_{time.strftime('%Y%m%d_%H%M%S')}_{seed}")
    if shutil.which("ffmpeg"):
        subprocess.run(["ffmpeg", "-y", "-loglevel", "error", "-framerate", str(FPS), "-i", os.path.join(tmp, "%04d.png"),
                        "-c:v", "libx264", "-crf", "20", "-pix_fmt", "yuv420p", "-movflags", "+faststart", nazwa + ".mp4"], check=True)
        shutil.rmtree(tmp, ignore_errors=True)
        print(f"Done: {nazwa}.mp4 ({len(imgs)} frames, {czas:.0f} s)")
    else:
        shutil.move(tmp, nazwa + "_klatki")
        print(f"Done: PNG frames in {nazwa}_klatki ({czas:.0f} s). Install ffmpeg to get MP4.")


if __name__ == "__main__":
    main()
See also: Wan AI: all versions, prices and my tests with videos · Wan 3.0 vs Wan 2.2 on the same prompts
A GPU result is not a minimum requirement
On November 8, 2026 I clarified the hardware claims and how to read the measurements. The clips, script and timings remain from September 26; I did not run a new benchmark for this update.
The official TI2V-5B card describes a reference command for at least 24 GB of VRAM, using model offloading, dtype conversion and a CPU text encoder. That is a configuration statement, not a promise that every ComfyUI graph has the same requirement. My installed files and settings are recorded above. Mixing those two implementations would make the memory comparison misleading.
I separate the first generation, which includes loading, from a warm run. A different checkpoint, resolution, frame count or offloading strategy changes the workload. A downloaded model fitting on disk also says nothing by itself about peak GPU memory. For another card, the useful record is the exact workflow plus a completed run, not the parameter count alone.
The project documentation distinguishes TI2V-5B from the larger variants. The documented 720p sizes are 704×1280 and 1280×704. For image-to-video, the input image supplies the aspect ratio and the size parameter specifies the area. I measured the landscape text-to-video configuration; this is not a portrait benchmark.
The energy calculation counts the graphics card during generation. The comparison table’s cloud prices are historical records, not a new quote. For a broader model comparison, use my Wan AI guide; for this experiment, use the dated measurements here.
Frequently asked questions
What GPU is needed for Wan 2.2?
My measured configuration was an RTX 4090 with 24 GB VRAM. The roughly 20 GB attributed to Wan excludes memory already occupied by the system and browser. I cannot turn that estimate into a minimum requirement for another GPU or another Wan variant.
How long does it take to generate a video in Wan 2.2?
About 4 minutes for a 5-second 720p clip (121 frames, 20 steps) on RTX 4090, when the model is already loaded. Generating the first clip after startup took 574 s because it included loading 18 GB of files from disk.
Is Wan 2.2 free and can you use it commercially?
The TI2V-5B weights are available without a model-license fee. Apache 2.0 permits commercial use under its terms. The roughly 0.02 kWh figure estimates the GPU energy for a warm generation, not the whole PC or the first model load. Hardware, storage and the rights to any source material are separate considerations.
Does Wan 2.2 TI2V 5B make video with sound?
No. The 5B version generates image only. Audio must be added in editing.
Does this test prove Wan 2.2 works on a 12 GB card?
No. It records a 24 GB RTX 4090 configuration. Offloading may help another setup, but it does not establish a tested minimum or a generation time for that card.
Does the electricity figure include the entire PC?
No. It estimates GPU energy for a warm generation. CPU, system memory, storage, cooling and model loading are outside that estimate.
Google · Your sourcesQuantslant higher in your Google - one clickAdd to preferred sources →Sources
- My test, September 26, 2026: RTX 4090 24 GB, ComfyUI 0.37, nvidia-smi readings every 0.5 s.
- Hugging Face - Wan-AI/Wan2.2-TI2V-5B (model card, Apache 2.0 license).
- Hugging Face - Comfy-Org/Wan_2.2_ComfyUI_Repackaged (files for ComfyUI).
- Hugging Face - Wan-AI organization (newest uploads: Wan2.2-Animate-2, August 2026).
- Checked on October 29, 2026.
Technical clarification sources checked on November 8, 2026:
- https://huggingface.co/Wan-AI/Wan2.2-TI2V-5B
- https://github.com/Wan-Video/Wan2.2
- https://huggingface.co/Comfy-Org/Wan-2.2
Frequently Asked Questions
What GPU is needed for Wan 2.2?
My measured configuration was an RTX 4090 with 24 GB VRAM. The roughly 20 GB attributed to Wan excludes memory already occupied by the system and browser. I cannot turn that estimate into a minimum requirement for another GPU or another Wan variant.
How long does it take to generate a video in Wan 2.2?
About 4 minutes for a 5-second 720p clip (121 frames, 20 steps) on RTX 4090, when the model is already loaded. Generating the first clip after startup took 574 s because it included loading 18 GB of files from disk.
Is Wan 2.2 free and can you use it commercially?
The TI2V-5B weights are available without a model-license fee. Apache 2.0 permits commercial use under its terms. The roughly 0.02 kWh figure estimates the GPU energy for a warm generation, not the whole PC or the first model load. Hardware, storage and the rights to any source material are separate considerations.
Does Wan 2.2 TI2V 5B make video with sound?
No. The 5B version generates image only. Audio must be added in editing.
Does this test prove Wan 2.2 works on a 12 GB card?
No. It records a 24 GB RTX 4090 configuration. Offloading may help another setup, but it does not establish a tested minimum or a generation time for that card.
Does the electricity figure include the entire PC?
No. It estimates GPU energy for a warm generation. CPU, system memory, storage, cooling and model loading are outside that estimate.
More on this from QUANTSLANT


 benchmarks·Mushroom Identification Apps: AI Test on 6 PhotosWe tested three AI models on six mushroom photos, including death caps. None allowed eating, but they confused boletes with bitter boletes.