RAG: How Retrieval-Augmented Generation Works and Where It Fails
RAG combines search with AI generation to answer questions from your documents. Here's how it works, when to use it, and where it typically breaks down.
👁 121 reads
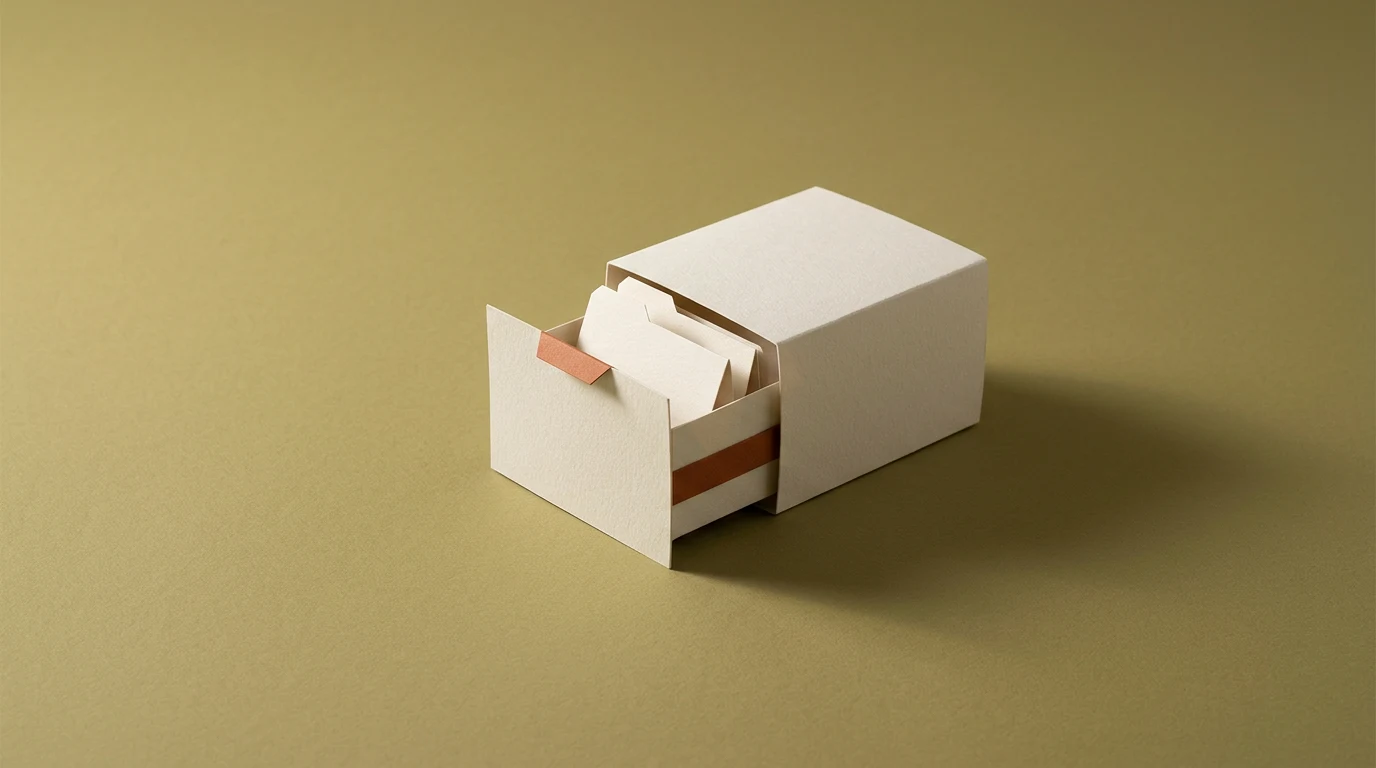
RAG stands for retrieval-augmented generation. Instead of relying on what a model remembers from training, the system first searches your documents for fragments matching the question, then asks the model to write an answer based on those fragments. It’s now the standard way to build assistants that answer questions about company documents, policies, or documentation.
How RAG works step by step
- Documents are split into chunks of a few hundred words.
- Each chunk is converted into a vector of numbers representing its meaning and stored in a vector database.
- The user’s question is also converted into a vector.
- The system finds several chunks closest to the question.
- The model receives the question along with those chunks and must answer based only on them, citing sources.
Why use RAG when you can paste a document into chat
With a single file, there’s really no need. RAG starts making sense with a thousand files that won’t fit in the context window, with documents that change weekly, and when answers must cite sources. The second reason is cost: the model receives only a few relevant paragraphs instead of an entire library, so the bill for tokens is dozens of times lower.
Where RAG breaks down
Poor document chunking. If a table or definition gets cut in half, the model receives half the meaning. Search by similarity, not meaning. A question about “fixed-term contract” can retrieve a fragment about permanent contracts because the vectors are close together. No information that something is missing. The model receives five irrelevant fragments and politely assembles something from them instead of saying it doesn’t know. That’s why good RAG systems always show sources and let you open them.
Google · Your sourcesQuantslant higher in your Google - one clickAdd to preferred sources →Common questions
Does RAG eliminate hallucinations?
It reduces them because the model answers from provided material, but doesn’t eliminate them. If the material is off-target, the answer will be hallucinated with a nice citation.
RAG or model fine-tuning?
For knowledge that changes, use RAG. For changing the style and format of responses, use fine-tuning. These two things solve different problems and are often used together.
Can you build RAG without coding?
Yes, ready-made knowledge base features are now available in company chat tools and automation platforms, for example n8n.
More on this from QUANTSLANT
 guides·Model Context Protocol (MCP): What It Is and How It WorksMCP is an open standard from Anthropic that lets AI models connect to data and tools through a unified protocol - like USB for AI assistants.