HiDream-O1-Video Review: Benchmark Rank, Pricing, and API
HiDream-O1-Video lands at #6 on Artificial Analysis (1175 Elo) at $5.80/min. Here is how its image-to-video API, vivago, and open weights actually work.
👁 120 reads
Regularly updated page. Current as of October 11, 2026.
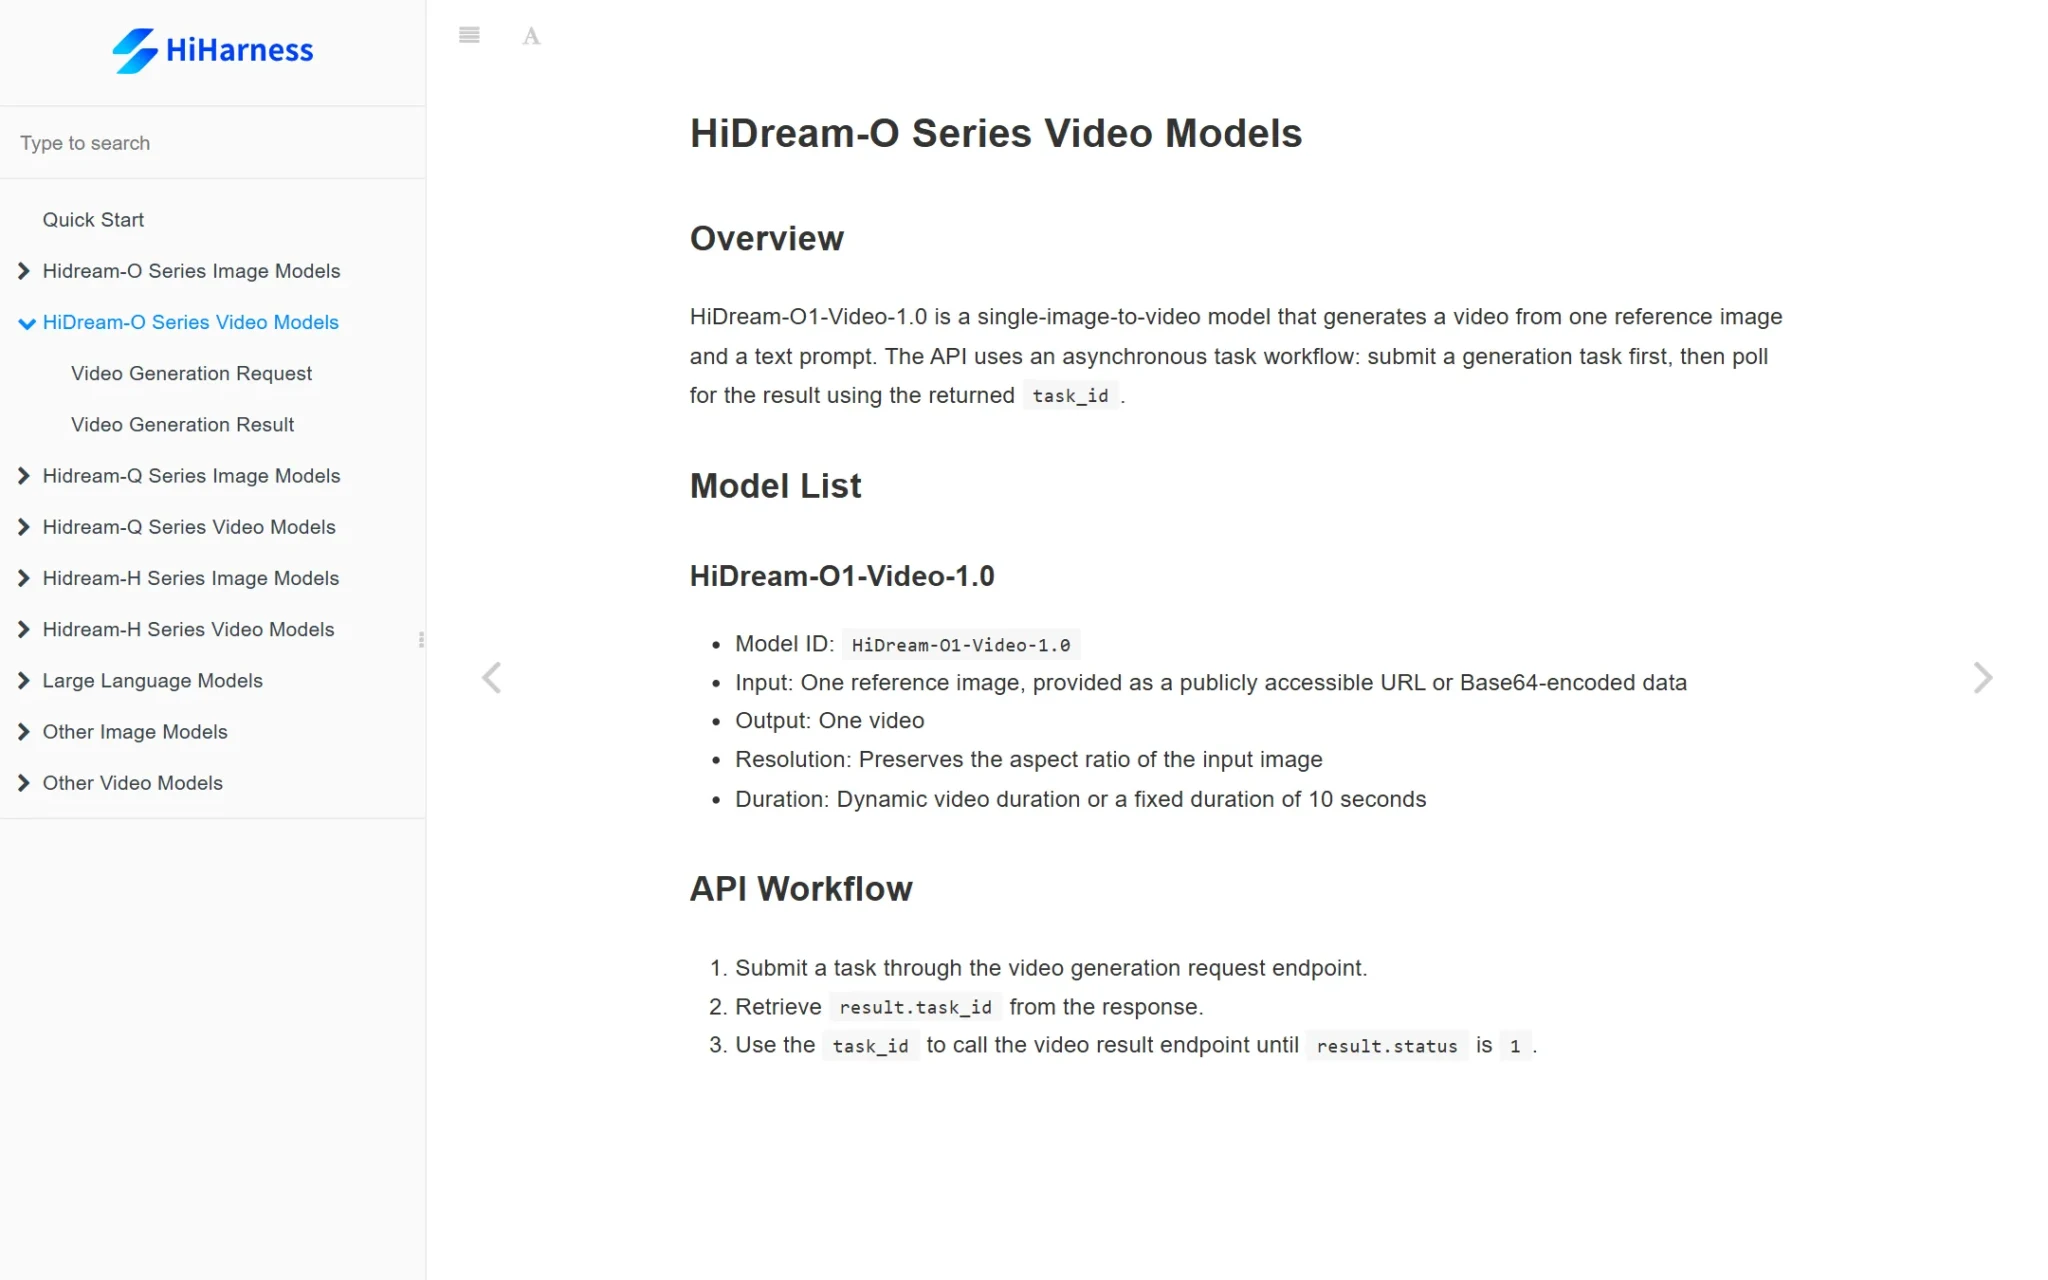
HiDream-O1-Video-1.0 is a video generation model from Beijing-based HiDream.ai that ranked 6th on the Artificial Analysis image-to-video leaderboard as of October 11, 2026 (1175 Elo points, 95% confidence interval 1165-1185). According to AA, it costs $5.80 per minute, undercutting most top-tier competitors. The catch: while marketing materials promised text, image, and video inputs, the public API only accepts a single image and an optional text prompt.
Status as of October 11, 2026
- Launch: September 15, 2026 in China (named HD-V1), followed by an English announcement on September 17. AA records its release date as August 28, 2026.
- Leaderboard rank: 6th in AA-Video-I2V v1.0, 1175 Elo across 3,231 comparisons. It is not listed on the text-to-video leaderboard.
- Public API: Image-to-video only (HiHarness). Text-to-video, video inputs, and reference editing currently exist only in marketing materials.
- Pricing: $5.80 per minute according to AA. HiDream has published no official API pricing sheet.
- Availability: vivago.ai (HiDream consumer app) and the HiHarness API. It is not hosted on fal.ai, Replicate, or OpenRouter.
- Open weights: No weights for the video model. Its sister image model, HiDream-O1-Image, is open-source under the MIT license.
- Hands-on test: Because O1-Video is not available through multi-model API aggregators or open weights, I could not generate custom video clips. However, I tested the open-weights HiDream-O1-Image model (via fal.ai on October 11) - details below.
What is HiDream-O1-Video and who is behind it?
HiDream.ai (Chinese: 智象未来) is an AI company based in Beijing’s Haidian District, founded in March 2023. It was created and is led by Dr. Mei Tao, a veteran researcher with 12 years at Microsoft Research Asia who later served as VP of Computer Vision at JD.com. Yao Ting serves as CTO. The company is best known for its visual models (HiDream-I1, E1, O1-Image) and its creative suite vivago.ai.
Funding is substantial. According to TechNode (September 18, 2026), HiDream closed a 1.5 billion yuan Series C round (around $221.6 million) in July 2026, reaching unicorn valuation. Since April 2026, it has raised over 2.1 billion yuan. The company claims more than 30 million users, over 40,000 enterprise clients, and over 400 million yuan in contracted revenue during Q1 2026.
O1-Video-1.0 is the first video model in the O1 family. The creator describes it as “natively omnimodal,” highlighting three core design focuses:
- Physical plausibility - gravity, inertia, collisions, material deformation, lighting, and spatial consistency.
- Pre-generation planning - the model orchestrates shot length, scene layout, character movement, facial expressions, camera trajectory, dialogue, and sound design before rendering frames.
- Model-determined shot duration - varying dynamically from 5 to 20 seconds depending on scene action, rather than hardcoded 5- or 10-second clips.
The model was trained using Diffusion RL alongside a multimodal reward model on HiDream’s proprietary UiT (Unified Transformer) architecture. HiDream has not published an academic paper for the video model; its paper on arXiv (2605.11061) covers O1-Image.
Artificial Analysis leaderboard ranking
The Artificial Analysis leaderboard is powered by blinded head-to-head comparisons: human judges evaluate two generated clips from identical source material and select the superior rendition. HiDream-O1-Video appears solely on the image-to-video chart (AA-Video-I2V v1.0), scoring 1175 Elo points with a 95% confidence interval of 1165-1185 (recorded October 11, 2026).
| Rank | Model | Provider | Elo | 95% CI | USD per minute (AA) |
|---|---|---|---|---|---|
| 1 | MiniMax H3 Max | MiniMax (hosted on Fal per AA) | 1195 | 1186-1204 | $4.80 |
| 2 | MiniMax H3 | MiniMax | 1181 | 1173-1189 | $7.80 |
| 3 | Vidu Q4 Preview | Vidu (ShengShu) | 1179 | 1169-1189 | $5.04 |
| 4 | Gemini Omni Flash | 1178 | 1171-1185 | $6.00 | |
| 5 | Seedance 2.0 720p | ByteDance | 1176 | 1169-1183 | $9.07 |
| 6 | HiDream-O1-Video-1.0 | HiDream | 1175 | 1165-1185 | $5.80 |
| 7 | Wan 3.0 | Alibaba | 1164 | 1156-1172 | $12.00 |
| 8 | HappyHorse-1.1 | Alibaba-ATH | 1104 | 1097-1111 | $9.90 |
Source: Artificial Analysis Image-to-Video Leaderboard, retrieved October 11, 2026. Confidence intervals rounded to whole integers.
Chart baseline begins at 1000 Elo (bar width = (Elo - 1000) / 2 percent) to emphasize performance deltas. Key takeaways:
- Positions 2 through 6 are effectively tied. HiDream trails MiniMax H3 by 6 Elo points, and the 95% confidence intervals across all five models overlap significantly.
- Only H3 Max pulls ahead cleanly (1195 Elo). HiDream’s upper confidence limit (1185) fails to reach H3 Max’s lower bound (1186).
- HiDream has fewer evaluated runs - 3,231 pairs compared to 15,721 for Seedance 2.0, giving it a comparatively wide confidence band.
- Launch standings fluctuated. HiDream initially publicized a 4th-place spot on AA’s “I2V With Audio” sub-board, while Arena.ai placed it 7th (1456 pts) in their own Image-to-Video Arena on September 30.
Hidream-O1-Video-1.0 by @HiDream_AI just landed in the Image-to-Video Arena at #7 with 1456 pts!
- Arena.ai (@arena) September 30, 2026
Specifications: Marketing announcement vs public API
This comparison reveals the biggest gap between early promotion and implementation. Press materials from mid-September claimed a model supporting text, image, and video inputs. In contrast, the HiHarness API documentation specifies a “single-image-to-video model.”
| Capability | Announcement (Sept 15-17, 2026) | Public HiHarness API (as of Oct 11, 2026) |
|---|---|---|
| Input modes | Text, image, video | Single image (required) + optional prompt and negative_prompt |
| Text-to-video | Yes | No |
| Video input, editing, reference clips | Yes | No |
| Duration | 5-20 s, dynamically determined by model | Dynamically chosen by model or locked to 10 s (force_10s) |
| Resolution | 1080p | No parameter; matches source image aspect ratio |
| Audio generation | Native, lip-synced speech generation | No parameter or mention in API docs |
| Input image format | - | URL or raw Base64, 40 KB to 20 MB |
| FPS, prompt limits, supported languages | Unspecified | Unspecified |
Sources: HiDream press release (Sept 17, 2026), QbitAI (Sept 15, 2026), HiHarness request documentation. OrcaRouter (Oct 10) and AlphaSignal (Oct 9) highlighted the same discrepancies. Read our detailed breakdown in HiDream-O1-Video API exposes image-to-video only.
How much does HiDream-O1-Video cost?
HiDream has not published an official developer price list for this model - an absence also noted by OrcaRouter. The only public figure is $5.80 per minute on the Artificial Analysis index (also cited by AlphaSignal). Based on that rate, estimated clip generation costs are:
| Clip length | Estimated cost at $5.80/min | Notes |
|---|---|---|
| 1 s | ~$0.097 | Per-second rate |
| 5 s | ~$0.48 | Minimum length advertised |
| 10 s | ~$0.97 | Generated when using force_10s |
| 20 s | ~$1.93 | Maximum length advertised |
Note: when allowing the model to choose duration dynamically, your final cost per generation is unpredictable. If predictable billing matters, set force_10s. For broader market context, see our guide on how much a second of AI video costs across models.
vivago.ai subscription plans
In the vivago web interface, usage is billed through tiered subscriptions. Pricing from vivago.ai (as of Oct 11, 2026):
| Plan | Annual billing | Monthly billing |
|---|---|---|
| Free | $0 | $0 |
| Basic | $7.90 / mo | $12.90 / mo |
| Plus | $19.90 / mo | $39.90 / mo |
| Pro | $59.90 / mo | $99.90 / mo |
Credit consumption per O1-Video run inside vivago remains unverified, as the platform does not reveal per-task token deductions before login.
Global availability and access
- vivago.ai - HiDream’s official web application. On September 30, @vivago_ai posted on X that O1-Video was “now available in vivago R1 Studio.” However, an October 9 press release covering the global rollout of vivago R1 stated that O1-Video would arrive “in an upcoming update.” Verify whether the model appears inside your Free account before subscribing.
- HiHarness (hiharness.ai) - HiDream’s developer platform. The model uses the endpoint ID
HiDream-O1-Video-1.0. Global availability for developer billing accounts remains unverified beyond regional portals. - Third-party aggregators - None as of October 11: absent from fal.ai, Replicate, WaveSpeed, OpenRouter (checked against 30 video models listed in
/api/v1/videos/models), Segmind, reAPI, kie, Pollo, and Higgsfield.
All three models are now available in vivago R1 Studio
- vivago.ai (@vivago_ai) September 30, 2026
Open weights and local deployment
You cannot download weights for the video model. As of October 11, it is missing from both HiDream-ai on Hugging Face and their GitHub repositories. It is a proprietary service available only via HiDream infrastructure.
However, the text-to-image foundation model from the same line, HiDream-O1-Image, is open-source under the MIT license:
- Includes Full and Dev checkpoints released May 8, 2026, alongside Dev-2604 from May 14, 2026 (model card, code).
- Features 9 billion parameters on Hugging Face, outputting resolutions up to 2048 x 2048.
- Hardware demands: officially listed only as a “CUDA GPU.” Community FP8 conversions (by drbaph) report roughly 10 GB VRAM usage, scaling to 17-20 GB in BF16/FP16 (unverified locally, suggesting standard 24 GB consumer GPUs suffice).
- The larger Pro variant (>200B parameters) remains closed-source.
Testing HiDream-O1-Image (image generation)
Note: this benchmark evaluates the open O1-Image model, not O1-Video. Because the video engine lacks open weights or aggregator endpoints, I could not run custom video tests. I tested the full O1-Image build on October 11, 2026 via fal.ai (endpoint fal-ai/hidream-o1-image) across 50 steps, guidance 5, seed 20261011. At fal’s rate of $0.01 per megapixel, two renders cost roughly $0.02. I assessed complex text rendering and prompt compliance. We tested it in Polish to evaluate its handling of regional diacritics alongside composition.
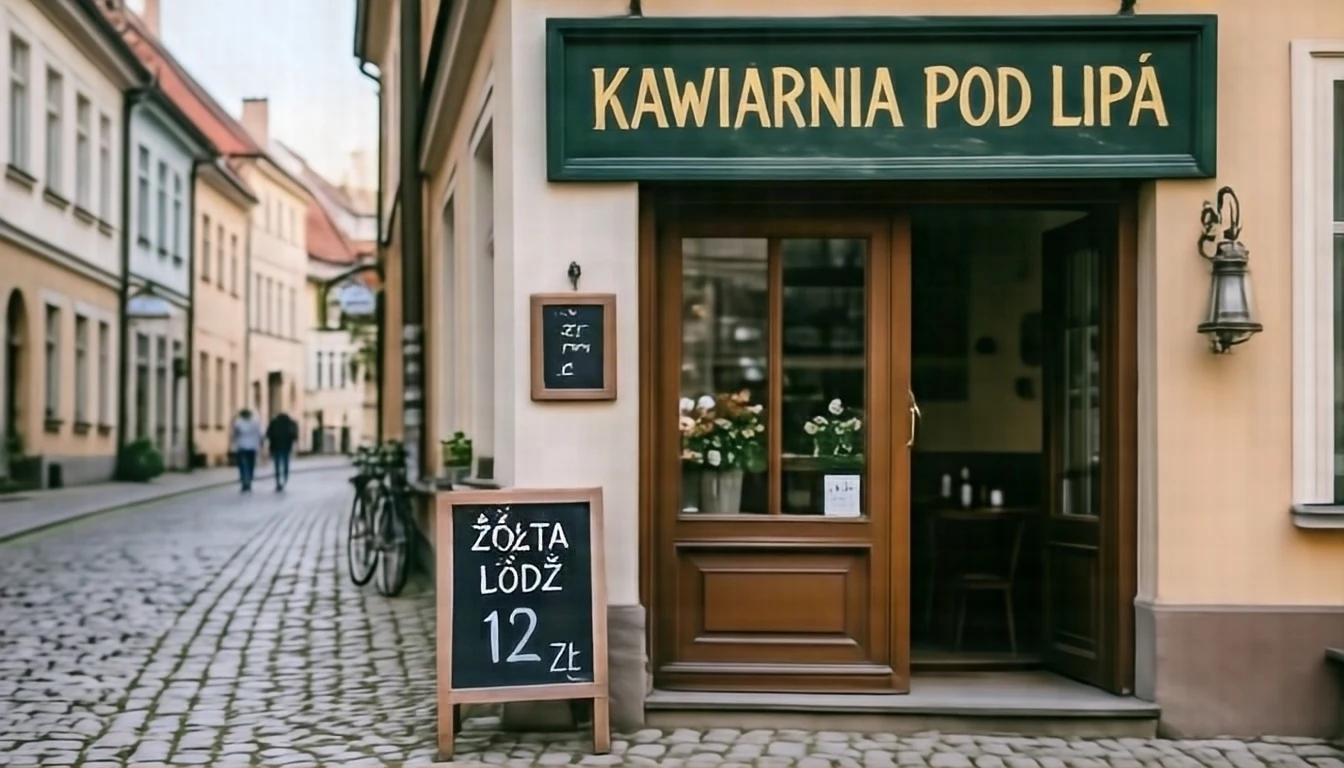
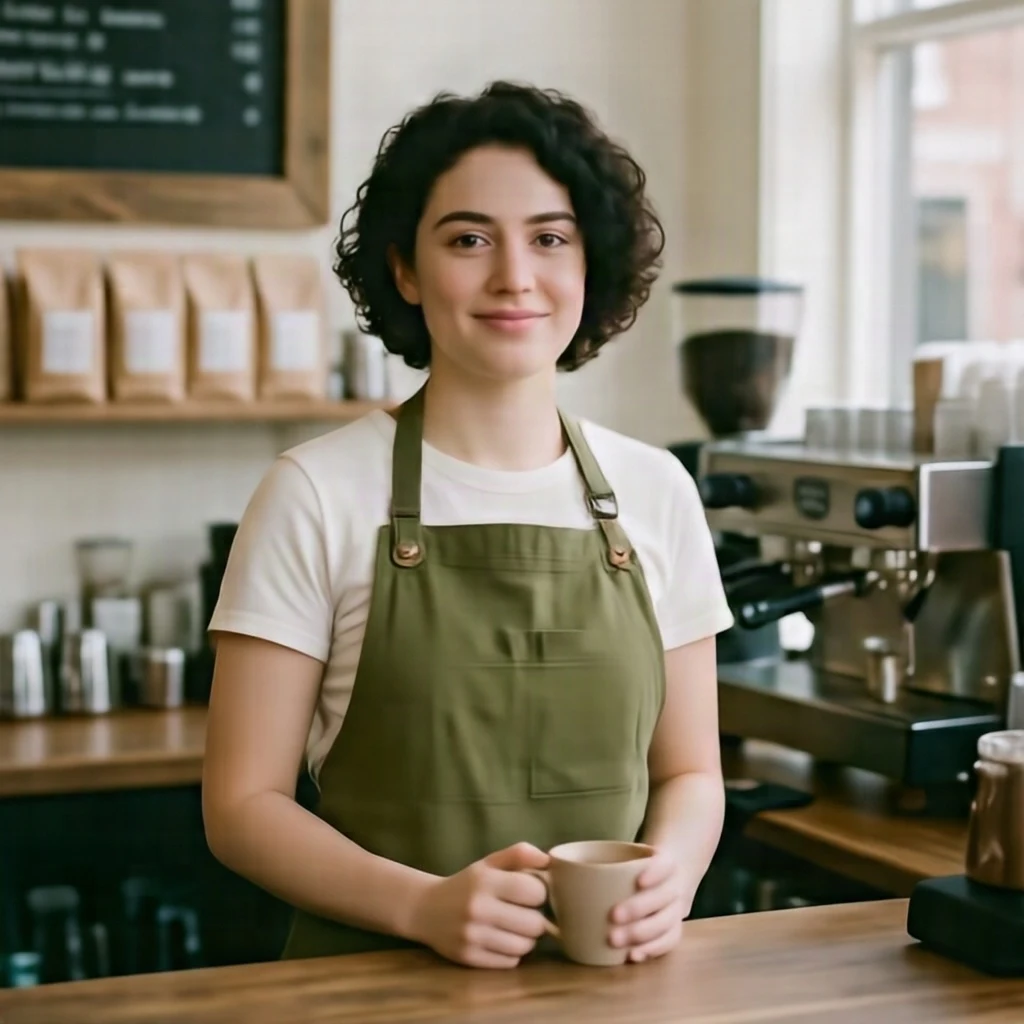
Key result: non-ASCII diacritics are inconsistent - failing on two out of eight special characters. Text elements must be inspected manually before using outputs as starting keyframes for video animation. Prompt adherence is solid overall, though the model occasionally populates neutral backgrounds unprompted.
A cost-effective workflow involves rendering starting keyframes locally with O1-Image and animating them via the O1-Video cloud API. For setting up your hardware, see our guide to running AI models locally, and see how O1-Image measures against alternatives in our open-source image model leaderboard. If you need open video weights, Artificial Analysis links weights only for MiniMax H3 (analyzed below) and MAGI-2.
How to get started: Step by step
Using the vivago web interface
- Navigate to vivago.ai/studio and create a Free account.
- Check the video model selector to ensure HiDream-O1 Video is available in your region.
- Upload your source keyframe - sharp, well-composed frames with clear subjects work best.
- Describe the desired motion in English: physical interactions, camera moves, and scene pacing. You can leave the duration setting to the model.
- Generate your clip and refine the prompt before considering a paid subscription.
Using the HiHarness REST API
- Register at hiharness.ai and obtain an API key.
- Send a POST request containing your source image (URL or raw Base64 without data URI prefixes, sized between 40 KB and 20 MB).
- Extract the
task_idfrom the JSON response. - Poll the status endpoint. Note:
result.status = 1indicates only that the server task completed. Real task status lives insub_task_results.task_status: 0 (queued), 1 (success), 2 (processing), 3 (generation error), or 4 (safety filter rejection). - Download your finished video from the provided
urlkey.
Sample cURL request based on official HiHarness documentation (replace with your private credentials; keep keys out of public version control):
curl --request POST 'https://hiharness.hidreamai.com/api/maas/gw/v1/videos/generations' \
  --header 'Authorization: Bearer <YOUR_API_KEY>' \
  --header 'Content-Type: application/json' \
  --data-raw '{
    "model_id": "HiDream-O1-Video-1.0",
    "image": "https://example.com/input.png",
    "prompt": "The subject turns toward the camera, with gentle cinematic motion",
    "negative_prompt": "blur, distortion",
    "request_id": "my-video-task-001"
  }'
The server returns result.task_id. Fetch generation results with:
curl --get 'https://hiharness.hidreamai.com/api/maas/gw/v1/videos/generations/results' \
  --header 'Authorization: Bearer <YOUR_API_KEY>' \
  --data-urlencode 'task_id=7aa15e3d-dcd6-4c27-9378-87ec97b2fbce'
Oddity in the documentation: the sample payload includes negative_prompt, even though it is absent from the documented parameter list (checked October 11, 2026). For ready-to-use prompts, explore our guide on what HiDream-O1-Video can do: prompt examples.
Comparison with competing video models
| Model | I2V Elo | 95% CI | USD/min (AA) | T2V on AA | OpenRouter (Oct 11) |
|---|---|---|---|---|---|
| MiniMax H3 Max | 1195 | 1186-1204 | $4.80 | Yes (1130) | Yes |
| MiniMax H3 | 1181 | 1173-1189 | $7.80 | Yes, 768p (1137) | Yes |
| Vidu Q4 Preview | 1179 | 1169-1189 | $5.04 | No | No |
| Gemini Omni Flash | 1178 | 1171-1185 | $6.00 | Yes, v1.1 (1113) | No |
| Seedance 2.0 720p | 1176 | 1169-1183 | $9.07 | Yes (1116) | Yes |
| HiDream-O1-Video-1.0 | 1175 | 1165-1185 | $5.80 | No | No |
| Wan 3.0 | 1164 | 1156-1172 | $12.00 | Yes, #1 rank (1156) | Yes |
Metrics via Artificial Analysis as of October 11, 2026. Aggregator availability checked on OpenRouter’s public model directory. HiDream matches the output quality of H3, Vidu Q4, Gemini, and Seedance, and places 3rd on cost behind H3 Max and Vidu Q4. However, it lacks text-to-video capabilities and third-party API availability. See our side-by-side analysis in HiDream-O1-Video vs MiniMax H3 vs Vidu Q4. For visual evaluations across identical scenes, see our multi-model test in the AI Video Arena.
Who should use HiDream-O1-Video?
- Creators animating static artwork or photography - product shots, UI renders, or mid-journey outputs. This is the model’s single supported API mode, and output quality rivals the leaders.
- Complex physics scenes - realistic bounces, projectile paths, fluid movements, and structural cloth behavior featured heavily in company showcases.
- Pipelines using open-weights O1-Image - combining free local generation for frames with cloud-based motion processing.
Skip it if you:
- Need pure text-to-video prompts - use Wan 3.0 or MiniMax H3 Max instead.
- Require explicit control over resolution, framerate, audio tracks, or exact runtime - the API does not expose these controls.
- Seek the absolute best quality-to-cost ratio - H3 Max scores higher at a lower rate per minute.
Explore broader options in our guide to the best AI video generators.
Related coverage
Frequently asked questions
Does HiDream-O1-Video support text-to-video?
While announced as a multimodal video generator, its public API (HiHarness, October 11, 2026) only accepts an image input with optional text guidance. It is unranked on Artificial Analysis’s text-to-video benchmark.
How much does HiDream-O1-Video cost to run?
Artificial Analysis quotes $5.80 per minute of output, equaling roughly $0.48 for a 5-second clip and $0.97 for a 10-second render. HiDream provides no public self-service rate sheet.
Can you use HiDream-O1-Video for free?
vivago.ai includes a Free tier, but generation allocations for O1-Video remain unconfirmed, and platform announcements about studio rollout dates have conflicted.
Can you run HiDream-O1-Video locally?
No. Weights for the video model are proprietary. You can, however, self-host HiDream-O1-Image under an open MIT license.
Does HiDream-O1-Video generate audio?
Marketing materials promised synchronized audio and realistic lip sync. The developer API provides no audio toggles or sound controls, leaving native sound generation unverified via API.
How long are the generated video clips?
The model defaults to dynamic pacing (5-20 seconds). In the API, you can leave duration to the engine or enforce a fixed 10-second render via the force_10s parameter.
Which languages does the prompt engine support?
HiDream does not list supported prompt languages. English prompts remain the safest choice for consistent motion and aesthetic results.
Sources and review dates
- Artificial Analysis Image-to-Video and Text-to-Video Leaderboards (retrieved October 11, 2026)
- HiDream Press Release via Media Outreach (September 17, 2026)
- QbitAI and Jiemian coverage (September 15, 2026)
- TechNode on HiDream funding round (September 18, 2026)
- HiHarness API documentation: requests and responses (retrieved October 11, 2026)
- vivago.ai subscription plans (October 11, 2026)
- vivago R1 global release release (October 9, 2026)
- OrcaRouter on API feature differences (October 10, 2026), AlphaSignal report (October 9, 2026)
- HiDream-O1-Image repository, drbaph FP8 conversion (October 11, 2026)
- Social updates on X: Arena.ai, vivago.ai (September 30, 2026)
 HiDream-O1-Video API Launches with Image-to-Video OnlyNews
 Vidu Q4 Preview: AI Video Benchmark Rank, Pricing, and GuideAI Tools
 HiDream-O1-Video vs MiniMax H3 Max vs Vidu Q4 vs Seedance 2.0Benchmarks
The link to Higgsfield is a partner link: if you buy through it, QUANTSLANT earns a commission and you pay the same price. It has no influence on the content, including where the coverage is critical.


