Qwen-Image-2.1 Benchmark: Full Rankings of 29 Image Models
The maker published a chart comparing 29 image models. We extracted the numbers and matched them with model sizes - a 7B model beats an 80B one by over nine points.
👁 115 reads
The maker of Qwen-Image-2.1 published a chart at launch comparing 29 image models - both open and closed. No one provided it as a table, so we extracted the numbers from the chart and matched them with model sizes. The result is more interesting than the ranking position alone.
Verdict in One Paragraph
Qwen-Image-2.1 takes seventh place with a score of 60.28 points in the Qwen-Image-Bench ranking. Ahead of it are exclusively closed models whose makers don’t disclose their size. What’s more interesting is what happens behind it: it beats Nano Banana 2.0, GPT Image 1.5, Seedream 5 Pro and Nano Banana Pro, as well as FLUX 2 Max, which is four times larger, and Hunyuan Image 3.0 - eleven times larger. This is a 7-billion-parameter model beating an 80-billion one by over nine points.
Full Qwen-Image-Bench Rankings
Numbers extracted from the chart published by the maker. The size column is empty where the model’s maker doesn’t disclose it - marked with a lock icon on the chart.
| # | Model | Score | Size |
|---|---|---|---|
| 1 | GPT Image 2.5 Sunburst | 67.01 | undisclosed |
| 2 | GPT Image 2 | 64.69 | undisclosed |
| 3 | Grok Imagine 2.0 | 63.47 | undisclosed |
| 4 | Qwen Image 3 Pro | 62.36 | undisclosed |
| 5 | Muse Image | 62.34 | undisclosed |
| 6 | MAI Image 2.5 Pro | 61.02 | undisclosed |
| 7 | Qwen-Image-2.1 | 60.28 | 7B |
| 8 | Nano Banana 2.0 | 59.82 | undisclosed |
| 9 | GPT Image 1.5 | 59.65 | undisclosed |
| 10 | Seedream 5 Pro | 59.53 | undisclosed |
| 11 | Nano Banana Pro | 59.45 | undisclosed |
| 12 | Grok Imagine Quality | 58.47 | undisclosed |
| 13 | Qwen Image 2.0 Pro | 57.84 | undisclosed |
| 14 | Seedream 5.0 | 57.22 | undisclosed |
| 15 | Seedream 4.5 | 56.78 | undisclosed |
| 16 | Seedream 4.0 | 56.21 | undisclosed |
| 17 | FLUX 2 Max | 55.33 | 32B |
| 18 | FLUX 2 Pro | 54.57 | 32B |
| 19 | GPT Image 1 | 54.07 | undisclosed |
| 20 | Qwen Image 2512 | 52.06 | 20B |
| 21 | Imagen 4.0 Ultra | 51.99 | undisclosed |
| 22 | Boogu | 51.40 | 10B |
| 23 | Hunyuan Image 3.0 | 50.81 | 80B |
| 24 | Imagen 4.0 | 50.29 | undisclosed |
| 25 | Qwen Image | 49.23 | 20B |
| 26 | Kling Image 2.1 | 48.26 | undisclosed |
| 27 | GLM Image | 48.19 | 16B |
| 28 | LongCat | 46.34 | 6B |
| 29 | HiDream O1 | 46.17 | around 8B |
A disclaimer that must be stated plainly: this is a benchmark published by the maker of one of the evaluated models. Treat it as vendor material, because that’s what it is. This doesn’t mean the numbers are fabricated - it means the task set and scoring method were chosen by a party with an interest in the outcome.
Three Things You Only See After Matching With Size
1. Jump Within Its Own Family
| Release | Size | Score |
|---|---|---|
| Qwen Image | 20B | 49.23 |
| Qwen Image 2512 | 20B | 52.06 |
| Qwen-Image-2.1 | 7B | 60.28 |
A nearly three-times-smaller model gets 8.22 points more than its direct predecessor. This isn’t a regular update, but a different architecture - single-stream layers, mixed-granularity attention, and key-value cache reuse.
2. Size Stopped Being a Pass to the Top
Hunyuan Image 3.0 has 80 billion parameters and a score of 50.81. Qwen-Image-2.1 has 7 billion and 60.28. The difference is an eleven-fold size advantage for the loser.
Practical consequence for someone counting hardware: the model that gives a better result fits on a single consumer card, while the larger one requires a server room. This is an opinion: for most use cases, this closes the discussion about which to choose.
3. Closed Models Still Lead, But the Gap Has Shrunk
It’s 6.73 points behind the leader, 3.19 behind third place. An open model you can run at home is today five points behind the top tier, not twenty. Behind it, however, are models you pay for per image.
What the Model Got in This Release
The maker lists four changes:
- Compact architecture - 32 DiT layers, mixed-granularity attention, key-value cache reuse with multiple input images.
- Native transparency - ability to specify in the prompt that an image should have an alpha channel, and cutting objects from photos as layers. We tested this with measurements.
- Editing - up to ten reference images, indicating edit location with a circle, paint-over, or mask, preserving identity of people and appearance of products.
- Textures and typography - better light on portraits and text layout that accounts for typeface and composition.
Plus panoramas from a single photo, infographics, and storyboards from character sheets.
How We Tested It Locally
We set up the model locally on an RTX 4090 and ran six tests. Two conclusions not found in the maker’s materials:
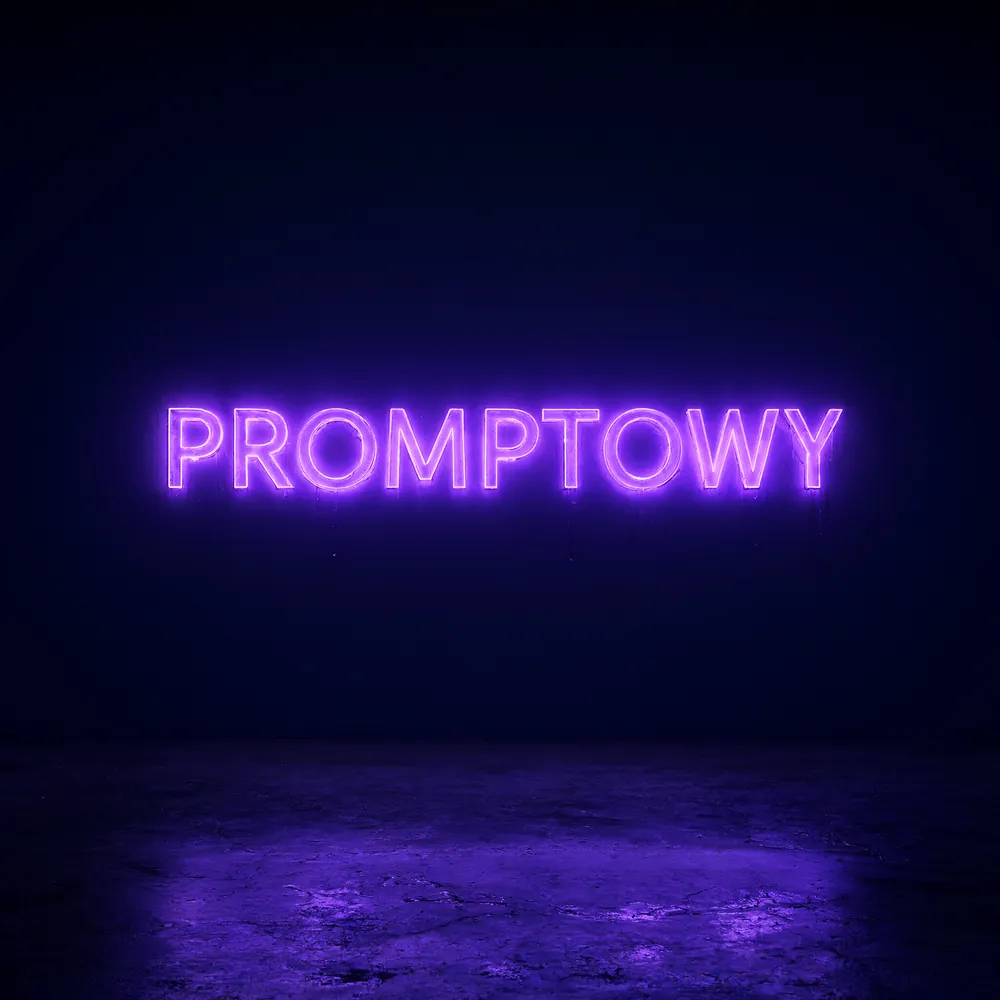
Neon sign with the text [BRAND] generated locally at 2048×2048 resolution - text came out flawlessly on the first try.
- Text actually matches. A neon sign with the text [BRAND] at 2048×2048 came out flawlessly on the first try.
- Prompts about character age are sometimes ignored. A request for a portrait of a woman in her thirties produced a visibly older person - technically excellent, but not matching the prompt.
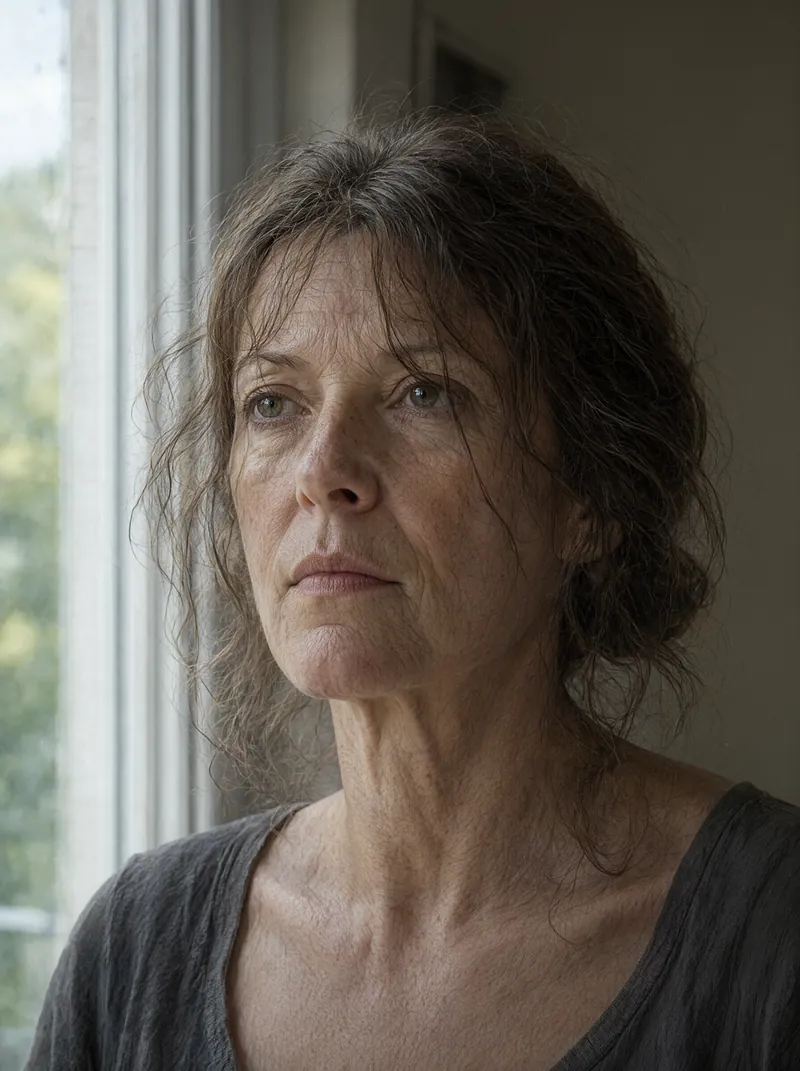
Portrait from a prompt about a woman in her thirties. Skin texture and light flawless, character’s age clearly higher than requested.
Timings, settings, and a ready script are in the installation guide, and we collected everything in the model guide.
What the Results Look Like in Practice
A ranking is one number. Below are three frames from three different categories, so you can see what’s behind that number.
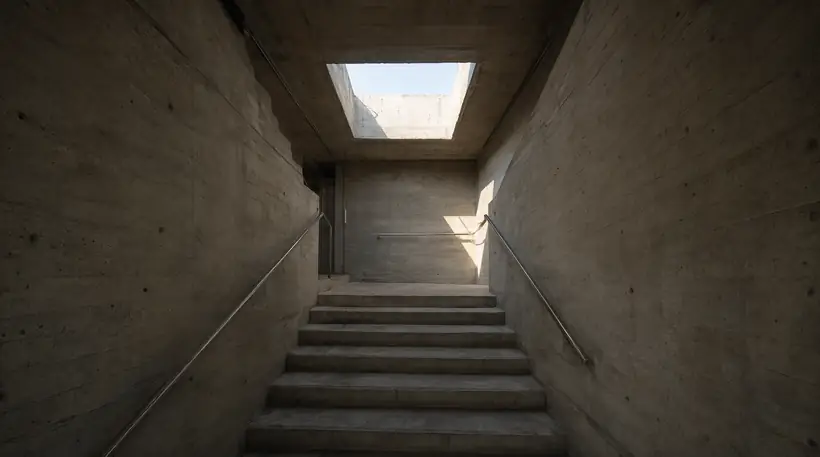
Architecture - the category where the model performs strongest.
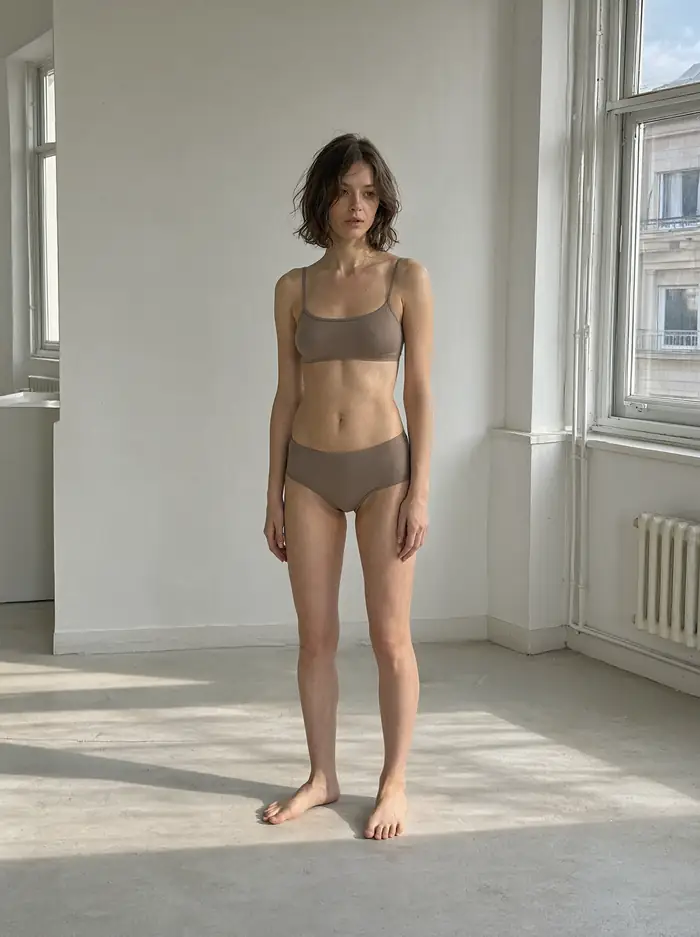
Available light - the model opts for documentary look over campaign aesthetics.
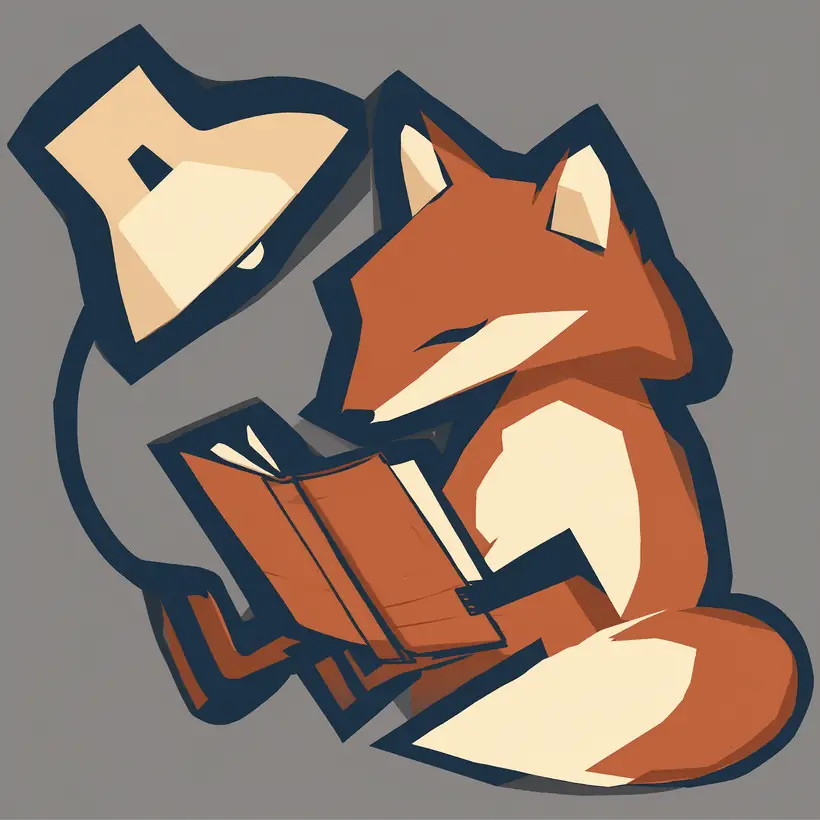
Vector illustration - correct, but generic. Here you see the limit.
Frequently Asked Questions
What score does Qwen-Image-2.1 have in the benchmark?
60.28 points in Qwen-Image-Bench, seventh place among 29 compared models.
Is this the best open image model?
In this comparison, yes - it beats FLUX 2 Max (55.33), Hunyuan Image 3.0 (50.81), and GLM Image (48.19). Remember that the ranking comes from the maker.
How many parameters does it have?
7 billion in the image-generating part, in 32 single-stream DiT layers.
Which model wins the ranking?
GPT Image 2.5 Sunburst with a score of 67.01, ahead of GPT Image 2 (64.69) and Grok Imagine 2.0 (63.47).
Is it better than Nano Banana?
According to this ranking, yes: 60.28 versus 59.82 for Nano Banana 2.0 and 59.45 for Nano Banana Pro. The difference is small, however.
Sources and Verification Date
- Results extracted September 22
- 2026 from the Qwen-Image-Bench chart published in the launch announcement at qwen.ai
- architecture and feature descriptions from the same announcement and from the model card Qwen/Qwen-Image-2.1. The maker provided this data as a chart
- not a table - the numbers in the table above are our editorial extraction from that chart. Observations about text and character age come from our own tests on RTX 4090
More on this from QUANTSLANT



 benchmarks·Qwen-Image-2.1 “Uncensored” Versions: What Official Weights DoWhen you run Qwen-Image-2.1 locally, there's no filter to remove - because the filter was never in the weights. We tested what the official model actually does.